Monitor and Maintain the Data Lakehouse
The Spark Executions page in C3 AI Studio is the primary user interface for monitoring Spark workloads. The page tracks every query that ran on a cluster, with filters by status, user, and origin, and a details dialog for each run. Cluster-lifecycle events and execution logs from a Python session also appear on the same page. The From a notebook section shows how to opt into logging and run table-maintenance procedures that the user interface does not expose.
Prerequisites
- Access to a SparkCluster and a C3 AI Data Lakehouse-enabled application.
- Familiarity with Spark SQL or PySpark and the Apache Iceberg table format.
- For Spark Connect usage, a Spark cluster that supports Spark 3.4+ (Spark Connect became generally available in 3.4).
In C3 AI Studio: Spark Executions page
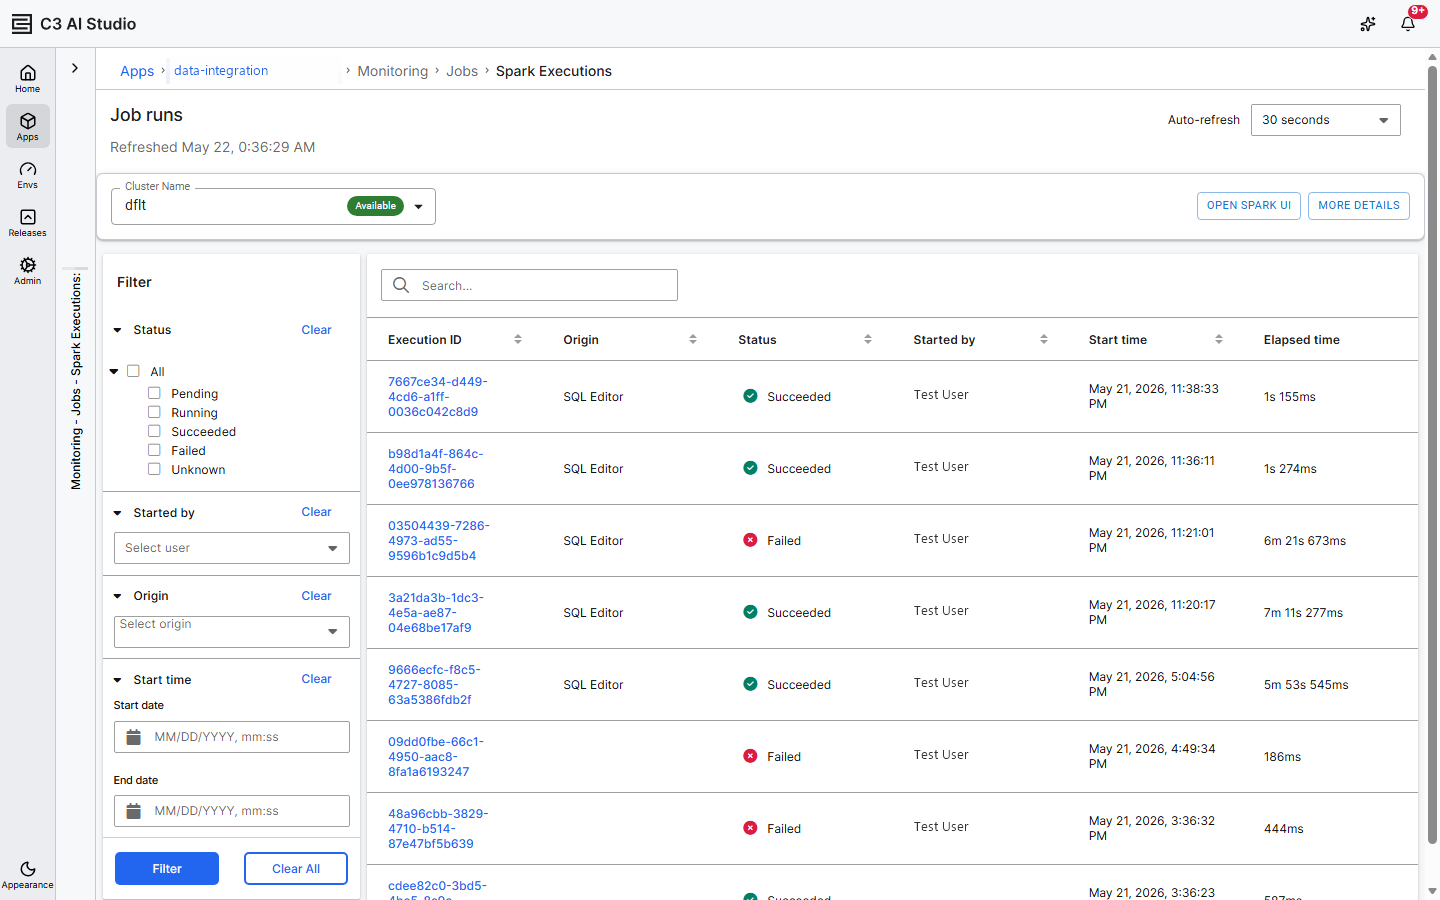
The Spark Executions page is the primary user interface for monitoring Spark workloads. Find the page under Monitoring > Jobs > Spark Executions in your application's side navigation.
The page is composed of three areas: a cluster status bar, a filter panel, and a results grid.
Cluster status bar
The cluster status bar shows the selected cluster's status and recent lifecycle events.
- Cluster: Selector that lists every cluster visible to you, with each cluster's current status. Common statuses are
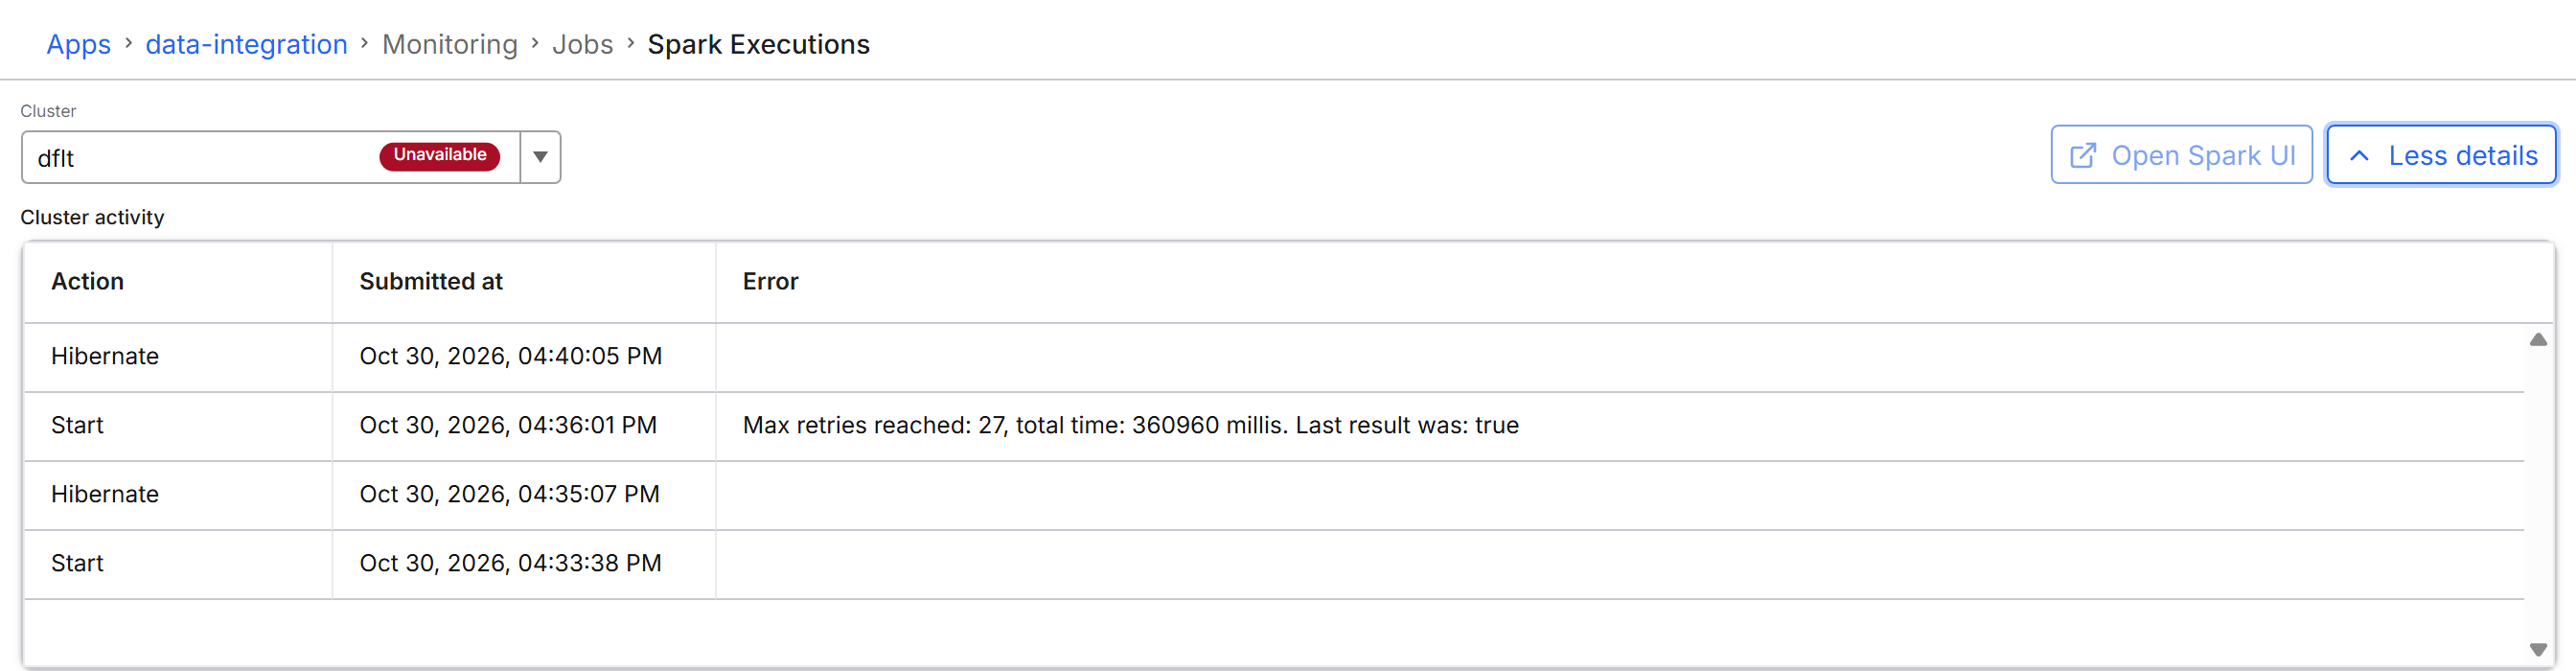
Running,Hibernated, andPending; a cluster may also displayUnavailablewhen the backing app is stopped or the cluster cannot be reached. - Open Spark UI: Opens the embedded Apache Spark UI for the selected cluster. The button is disabled when the cluster is not Running.
- More details: Expands a Cluster activity grid showing Hibernate and Start events with timestamps and any error messages. Use the grid when investigating cold-start delay or a failed restart.
Filter panel
The filter panel narrows the grid to a subset of executions.
- Status: Pending, Running, Succeeded, Failed, Unknown. An All toggle selects every status at once.
- Started by: Filter by the user who submitted the query.
- Origin: Filter by where the query came from. The SparkExecutionOrigin enum defines two values:
SQL Editor(queries submitted through the SQL Editor) andSource to DataLake(writes from a Data Fusion pipeline's Load to Data Lakehouse step). Runs from a notebook are not tagged with an enum value. - Started: Start date and End date pickers for the submission time.
Results grid
| Column | Description |
|---|---|
| Execution ID | Unique identifier; select to open the execution details. |
| Origin | Where the query came from: SQL Editor or Source to DataLake. |
| Status | Current state. |
| Started by | The user who submitted the query. |
| Start time | Submission time. |
| Elapsed time | Time in the queue plus time on the cluster. |
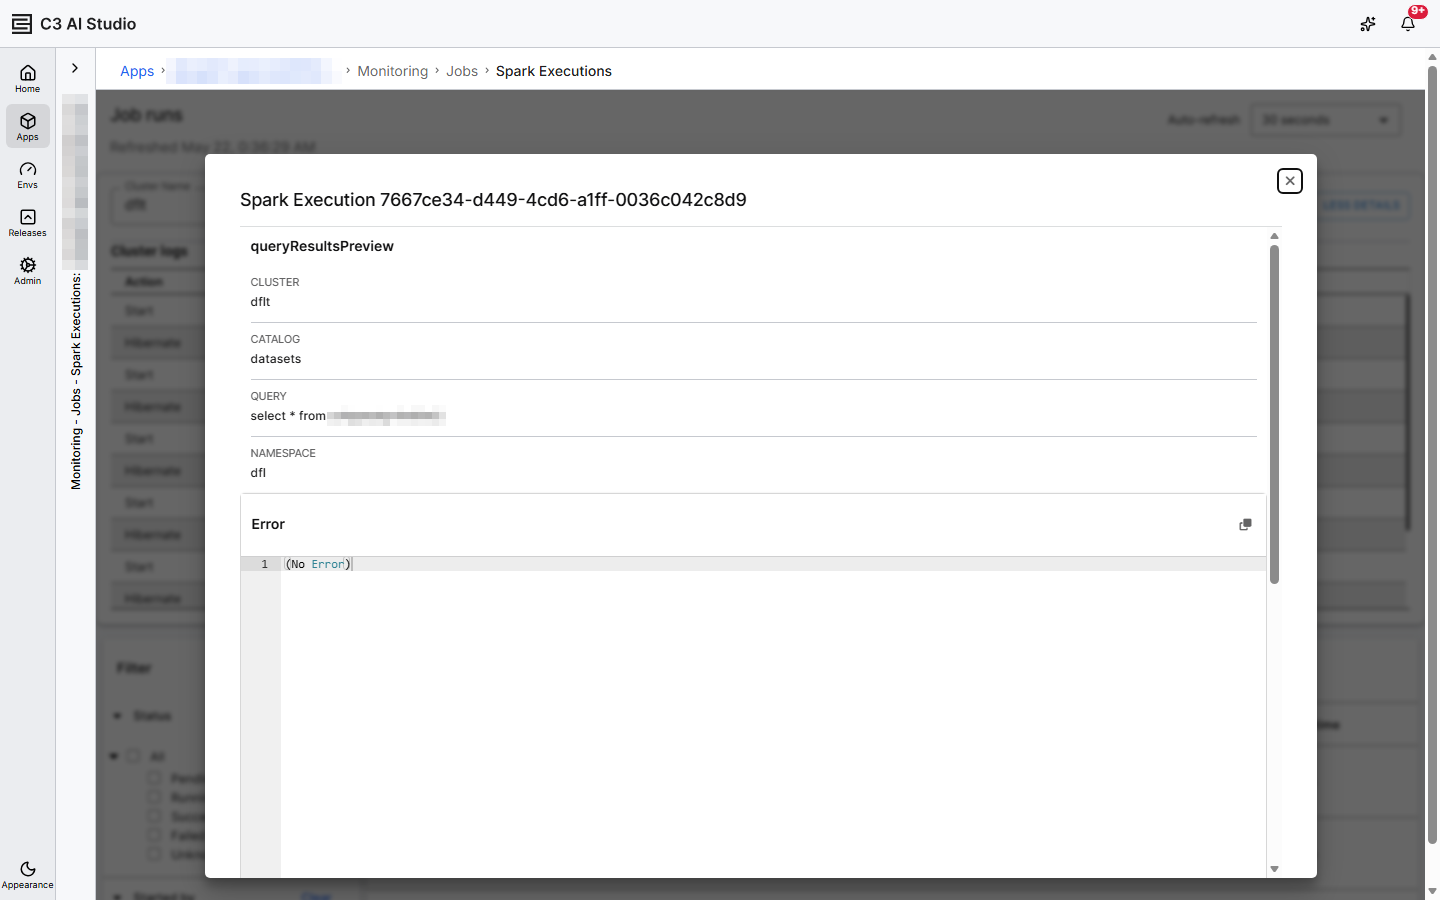
The execution details show the cluster, catalog, namespace, query text, and the error message (if any). Copy the query or the error to debug it, or paste the query into the SQL Editor to run it again.
First query after idle
When the selected cluster is hibernated and a query arrives, the SQL Editor displays the message The Spark cluster is starting up. The query will run once the cluster is available. The query queues until the cluster reaches the Running state. Cold start can take several minutes; subsequent queries against a warm cluster return in seconds.
From a notebook
The Spark Executions page is the primary surface for monitoring. The following sections cover the notebook-only paths: opting into per-session logging, managing the cluster lifecycle, expiring snapshots, and compacting small files. The user interface does not expose these operations directly.
Enable logging on a Data.SparkSession
When initializing a Data.SparkSession, set enableLogging=True to capture execution logs. All operations triggered from that session are logged into the SparkExecution type and appear on the Spark Executions page.
Queries that you run in the SQL Editor are logged too. SQL Editor queries appear in the same log as queries from a Jupyter or Console session.
The following example starts a session with logging on and runs a small operation:
cluster = c3.SparkCluster.inst()

ss = cluster.dataSparkSession(enableLogging=True)

spark = cluster.sparkConnectSession()ss.read_csv("gcs://c3--datasets/iris.csv").shapeThe call returns (150, 5). To see the logged execution from a notebook:
c3.SparkExecution.fetch()The fetch returns a SparkExecution row for the read; the same row is visible on the Spark Executions page in the user interface.
Manage the cluster lifecycle
Spark clusters move through three runtime states: Running (actively servicing queries), Hibernated (idle, ready to resume on demand), and Terminated (configuration removed). Choose a state with the matching API.
cluster = c3.SparkCluster.inst()
cluster.stop()           # hibernate; preserves config and warm state
cluster.terminate(True)  # drop config; full clean-up
cluster.status             # current state
cluster.idleTimeMillis()   # time since the last activity
For Grafana metrics, the service ID is the lookup key:
cluster.serviceId()Paste the returned ID into the Spark Grafana dashboard to view detailed cluster metrics.
The platform seeds a cron job, spark-clean-idle-cluster, that can hibernate idle clusters. The job is inactive by default; enable it to hibernate idle clusters on a schedule. To inspect the job or change its schedule:
c3.CronJob.forId("spark-clean-idle-cluster")Expire snapshots
Snapshots accumulate as a table evolves. Use snapshot expiration to release the storage held by snapshots older than a retention window.
spec = (
    c3.DataLake.Table.ExpireSnapshotSpec.builder()
    .retentionWindow("1d")
    .minimumSnapshots(1)
    .build()
)
table.expireSnapshots(spec)
For the full snapshot lifecycle, including time-travel reads, tags, and rollback, see Manage Data Lakehouse Snapshots and Versions.
Compact small data files and remove orphans
The DataLake.Operations Type, which is in beta, provides data-file compaction (rewriteDataFiles) and orphan-file cleanup (deleteOrphanedFiles). C3 AI Studio does not expose either operation, and the Iceberg SQL procedures are not C3-supported against federated Lakehouse tables. To control storage growth without a beta API, expire snapshots, as described in Expire snapshots. For sustained low file counts, contact C3 AI support for the maintenance options available in your environment.