Confluence Connector
The Confluence connector gives C3 AI applications secure, read-only access to your Confluence content. You can retrieve pages, spaces, labels, attachments, blog posts, custom content, and tasks.
Prerequisites
To connect Confluence to C3 AI applications, make sure you have the following:
- An active Confluence account with permission to view the spaces or pages you intend to query.
- An API token for that account. See the Generate a Confluence API token section.
Confluence permissions apply to every API call. If your account cannot view an object in Confluence, you cannot fetch it through the API.
Authentication and configuration
Authenticate and configure the Confluence connector with a Confluence API endpoint, a username, and an API token. This configuration gives C3 AI applications read-only access to Confluence content.
Generate a Confluence API token
Create the token while signed in to the Confluence account that the connector uses:
- Open Confluence and go to Account settings.
- Select Security > API tokens.
- Select Create and manage API tokens.
- Select Create API token. Give the token a recognizable name and set a custom expiry of up to one year.
- Copy the generated token and store it securely.
After you close the dialog box, you cannot see the generated API token again. Keep the API token only until you enter it during setup. Once the configuration is complete, you can discard the API token.
Gather required fields
Collect these three values before you configure the connector:
- Endpoint: the endpoint of the Confluence API server you want to access, for example
https://<your-domain>.atlassian.net/wiki/api/v2/ - Username: the username (email) of the account that accesses the server. The username must match the account that generated the token.
- API token: the token used for authentication. See the Generate a Confluence API token section.
Configure Confluence credentials
To enable the Confluence connector, configure the Confluence API endpoint with the username and API token of your Confluence account. The following code builds a Base64-encoded Basic Authentication header from these values and registers it at the application level.
After you configure the connector, every API call authenticates against the specified Confluence instance with the permissions of the configured account.
// Setting credentials for Confluence
const endpoint = "https://<your-domain>.atlassian.net/wiki/api/v2/";    // API endpoint
const username = "<your-email>@example.com";                           // Atlassian account email
const token    = "<api-token>";                                       // API token from Confluence

// You can also set credentials at environment level if you want all applications to have access via the same account
// Same could apply to cluster level, assuming user has corresponding credentials
const credentials = `${username}:${token}`;
const auth = Base64.encodeString(credentials);

// Register the endpoint and auth for subsequent calls
Confluence.setApiUrlAndAuth(endpoint, `Basic ${auth}`, ConfigOverride.APP);Authorization behavior
The account you configure decides what each call returns:
- You can retrieve only content visible to the configured account.
- If the configured account lacks access to a space, page, or resource, the API returns an authorization error or an empty result set.
Common configuration issues
Use this table when a call returns an error or no results:
| Issue | Likely Cause | Resolution |
|---|---|---|
| 401 Unauthorized | Invalid or expired API token | Generate a new token and update configuration |
| 403 Forbidden | API token is valid but the Confluence account does not have access to view the space or page | Grant access to required spaces or pages |
| Empty results | The configured account cannot view the requested content | Verify access in the Confluence UI |
| 404 Not Found | Incorrect API endpoint | Update credentials if the endpoint is incorrect. Confirm the base URL includes /wiki/api/v2/ |
| 429 Too Many Requests | Connector temporarily exceeded Confluence's API limits | Try again after waiting a minute |
Usage patterns and examples
The following read-only retrieval APIs are available for Confluence:
- Pages
- Spaces
- Labels
- Attachments
- Blog posts
- Custom content
- Tasks
You can validate your Confluence credentials without the connector by making a direct REST API call with curl. See the Independent credential verification section for more information.
1. Pages
Description: Retrieve visible pages within a given space.
Parameters of ConfluenceService.listPages(ids, limit), which the examples call:
| Name | Type | Description |
|---|---|---|
| ids | [int] | Page IDs to retrieve. |
| limit | int | Maximum number of results. Default is 25, maximum is 250. |
Confluence.getPagesBySpace(id, limit) reads the pages of one space, and Confluence.getPagesByLabel(id, limit) reads the pages that carry one label. The examples on this page use both.
Related Confluence REST methods
getPages(id, sort): retrieves all visible pages, optionally filtered by IDs and sorted.
Examples
// List all visible pages
ConfluenceService.listPages()

// Retrieve pages for a space using space ID and you can limit the number of pages too
// getPagesBySpace(spaceId: int, limit: int)
Confluence.getPagesBySpace(<space-id>, 150)

// Filter listPages by the pageIds
ConfluenceService.listPages([139956775, 1186234406])
API Output
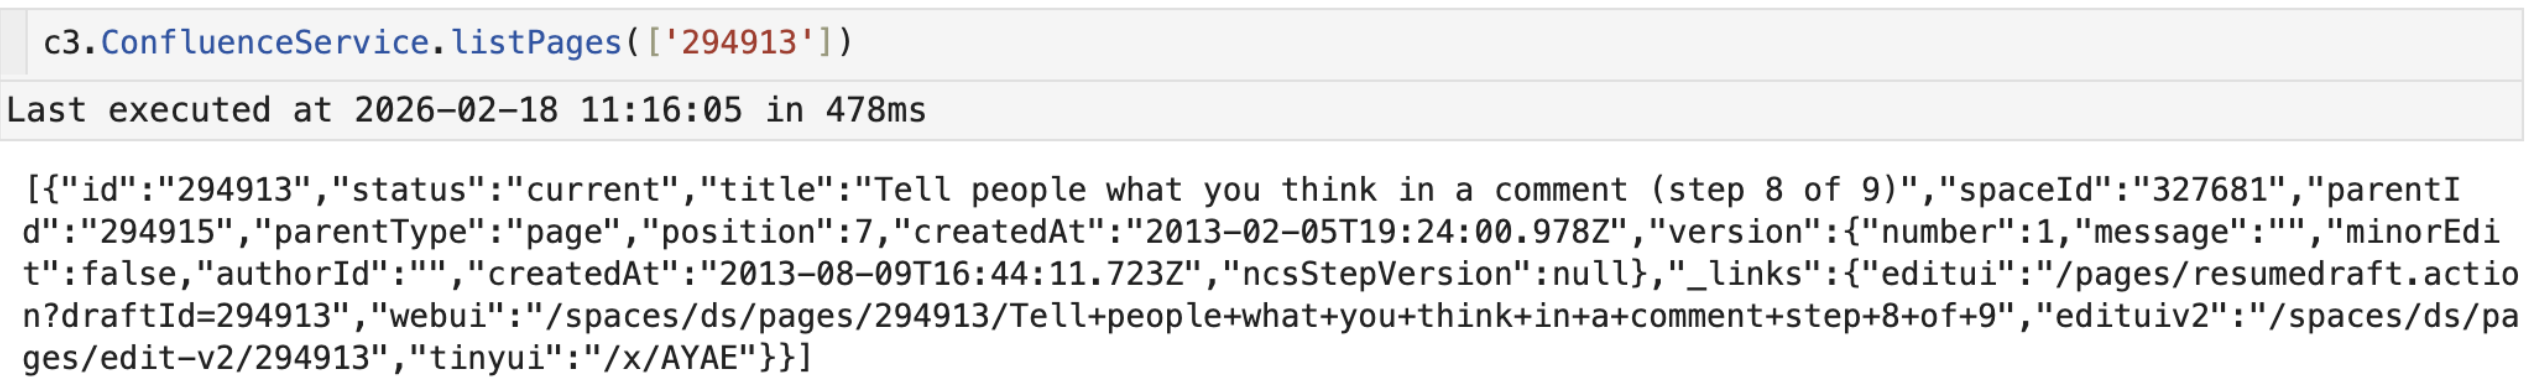 |
| Confluence Connector API Output for List Pages |
2. Spaces
Description: Retrieve visible spaces by their space ID.
Parameters of ConfluenceService.listSpaces(ids, keys, limit), which the examples call:
| Name | Type | Description |
|---|---|---|
| ids | [int] | Space IDs. |
| keys | [string] | Space keys, for example "<SPACE_KEY>". When you pass both ids and keys, the result is their intersection. |
| limit | int | Maximum number of results. Default is 25, maximum is 250. |
Related Confluence REST methods
getSpaces(ids, keys, sort): retrieves all visible spaces, with optional filtering by ID or key and sorting.getSpaceById(id): retrieves a space by its ID.
Examples
// List all visible spaces
ConfluenceService.listSpaces()

// Filter the listed spaces by the space IDs and the keys. You can also limit the number of results
// listSpaces(ids: [int], keys: [string], limit: int)
ConfluenceService.listSpaces(null, ["<SPACE_KEY>", "<SPACE_KEY_2>"])

// Can list all available spaces by increasing the limit to 100
ConfluenceService.listSpaces(null, null, 100)
API Output
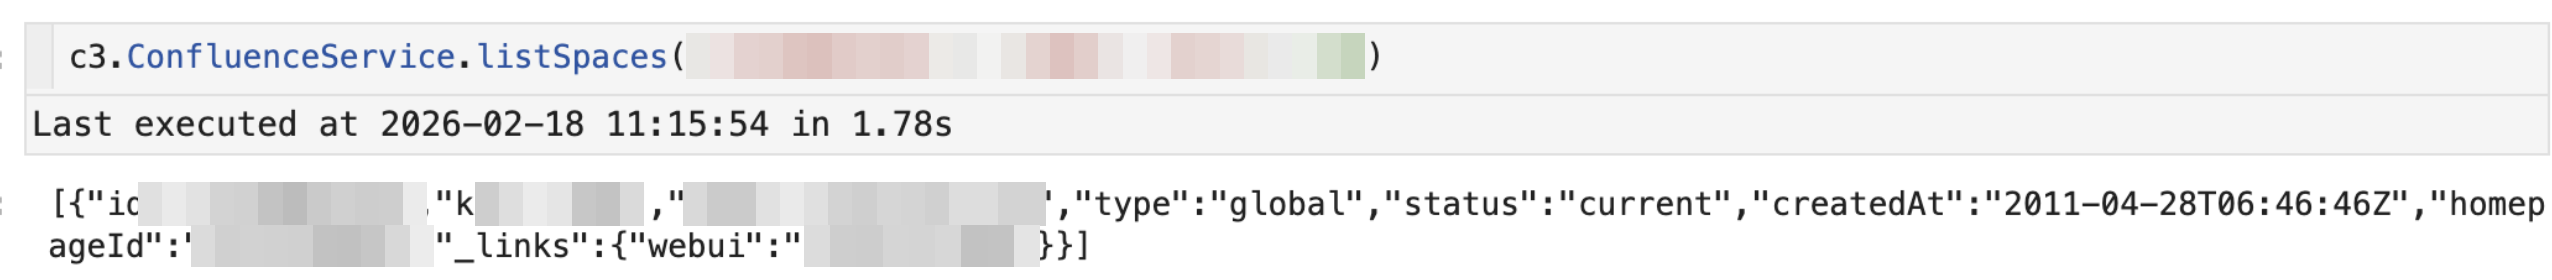 |
| Confluence Connector API Output for List Spaces |
3. Labels
Description: Retrieve visible labels associated with a specific space ID or page ID.
Parameters of ConfluenceService.listLabels(select, id, prefix, limit), which the examples call:
| Name | Type | Description |
|---|---|---|
| select | string | 'space' reads the labels of a space, 'page' reads the labels of a page, and any other value reads all labels. |
| id | int | The space or page ID. |
| prefix | [string] | Label prefixes to match. |
| limit | int | Maximum number of results. Default is 25, maximum is 250. |
Related Confluence REST methods
getLabels(prefix, sort): retrieves all visible labels, filtered by prefix and sorted.getLabelsByPage(id, prefix): retrieves labels associated with a specific page.getLabelsBySpace(id, prefix): retrieves labels associated with a specific space.
Examples
// List all visible labels
ConfluenceService.listLabels()

// Filter labels based on their spaceId, pageId as well as the value of the prefix.
// listLabels(select: string, id: int, prefix: [string], limit: int)
ConfluenceService.listLabels(null, null, ['team'], 100)

// Retrieve labels for a particular space by its ID.
ConfluenceService.listLabels('space', <space-id>)

// Retrieve labels for a particular page by its ID.
ConfluenceService.listLabels('page', 192479460)

// Retrieve all the pages which consist of a particular label by using the label ID.
Confluence.getPagesByLabel(2654210)4. Attachments
Description: Retrieve visible attachments across Confluence, with optional filtering and sorting.
Parameters of ConfluenceService.listAttachments(filename, mediaType, limit) and ConfluenceService.listAttachmentsByPage(id, filename, mediaType, limit), which the examples call:
| Name | Type | Description |
|---|---|---|
| id | int | Page ID. Required for listAttachmentsByPage. |
| filename | string | Filter by filename. |
| mediaType | string | Filter by MIME type, for example image/png or application/pdf. |
| limit | int | Maximum number of results. Default is 25, maximum is 250. |
Related Confluence REST methods
getAttachments(filename, mediaType, sort): retrieves all visible attachments, filtered and sorted as needed.getAttachmentById(id): retrieves a specific attachment by its ID.getAttachmentsByPage(id, filename, mediaType, sort): retrieves attachments belonging to a specific page.
Examples
// List all visible attachments
ConfluenceService.listAttachments()

// Filter listed attachments based on filename and mediaType.
// listAttachments(filename: string, mediaType: string, limit: int)
ConfluenceService.listAttachments(null, "image/png", 10)

// List all attachments for a page, given the page ID.
ConfluenceService.listAttachmentsByPage(139956775)5. Blog posts
Description: Retrieve visible blog posts, with optional filtering and sorting.
Parameters of ConfluenceService.listBlogPosts(ids, title, limit) and ConfluenceService.listBlogPostsBySpace(id, limit), which the examples call:
| Name | Type | Description |
|---|---|---|
| ids | [int] | Blog post IDs. |
| title | string | Filter by title. |
| id | int | Space ID. Required for listBlogPostsBySpace. |
| limit | int | Maximum number of results. Default is 25, maximum is 250. |
Related Confluence REST methods
getBlogPosts(id, title, sort): retrieves all visible blog posts, with filtering and sorting options.getBlogPostById(id): retrieves a specific blog post by its ID.getBlogPostsBySpace(id, limit): retrieves a limited number of blog posts from a specific space.
Examples
// List visible blog posts
ConfluenceService.listBlogPosts()

// List blog posts for a particular space
ConfluenceService.listBlogPostsBySpace(1857814531)

// Filter blog posts by their IDs or title
// listBlogPosts(ids: [int], title: string, limit: int)
ConfluenceService.listBlogPosts(null, "Enterprise Digital Transformation")6. Custom content
Description: Retrieve custom content entries (excludes pages, blog posts, and attachments).
Parameters of ConfluenceService.listCustomContent(type, spaceIds, ids, limit), which the examples call:
| Name | Type | Description |
|---|---|---|
| type | string | Content type key, for example com.atlassian.confluence.extra.teamcalendars:calendar-content-type. |
| spaceIds | [int] | Restrict to these spaces. |
| ids | [int] | Restrict to these content IDs. |
| limit | int | Maximum number of results. Default is 25, maximum is 250. |
Related Confluence REST methods
getCustomContent(type, spaceId, id, sort): retrieves custom content types (for example, calendars), excluding pages, blog posts, and attachments.
Examples
// List visible custom content
ConfluenceService.listCustomContent()

// Filter custom content by type, spaceIds, and IDs.
// listCustomContent(type: string, spaceIds: [int], ids: [int], limit: int)
// Filter custom content by type
ConfluenceService.listCustomContent("com.atlassian.confluence.extra.teamcalendars:calendar-content-type")

// Filter custom content by content IDs.
ConfluenceService.listCustomContent(null, null, [<content-id>, <content-id-2>])
7. Tasks
Description: Retrieve visible tasks with optional filters.
Parameters of ConfluenceService.listTasks(dueDateFrom, dueDateTo, spaceIds, assignedTo, status, limit), which the examples call:
| Name | Type | Description |
|---|---|---|
| dueDateFrom | DateTime | Earliest due date, inclusive. |
| dueDateTo | DateTime | Latest due date, inclusive. |
| spaceIds | [int] | Restrict to these spaces. |
| assignedTo | [string] | Account IDs of assignees. |
| status | string | Filter by status, for example open or complete. |
| limit | int | Maximum number of results. Default is 25, maximum is 250. |
Related Confluence REST methods
getTasks(spaceId, assignedTo, status): retrieves all visible tasks with optional filters (for example, space, assignee, or status).getTaskById(id): retrieves a specific task by its ID.
Examples
ConfluenceService.listTasks()

// Filter tasks based on due date, spaceIds, assignedTo and status
// listTasks: function(dueDateFrom: DateTime, dueDateTo: DateTime, spaceIds: [int], assignedTo: [string], status: string, limit: int)
ConfluenceService.listTasks(null, null, null, null, "complete", 5)

// Filter by a single assignee (accountId)
ConfluenceService.listTasks(null, null, null, ["<assignee account ID>"])

// Filter by date range with a higher limit
const dueAtFrom = DateTime.fromString("2017-06-20T00:00:00.000Z");
const dueAtTo   = DateTime.fromString("2017-06-25T07:00:00.000Z");
ConfluenceService.listTasks(dueAtFrom, dueAtTo, null, null, null, 250);Verification
After you configure the Confluence connector and apply the credentials, verify the connection by listing spaces.
Run the following command:
// listSpaces(ids: [int] | null, keys: [string] | null, limit: int)
ConfluenceService.listSpaces(null, null, 10)
When the connection is configured correctly, the command returns a list of spaces visible to the configured account.
Use the ConfluenceService APIs (C3 convenience functions) where you can. You can also call Confluence REST endpoints directly through the Confluence Type, such as Confluence.getPagesBySpace.
Independent credential verification
Validate your Confluence credentials without the connector by making a direct REST API call with curl. This check confirms that the account and API token are valid and have the required permissions, before you troubleshoot connector behavior further. See Basic auth for REST APIs for configuration details and examples.