Microsoft Fabric OneLake as an Azure File System
Microsoft Fabric OneLake provides an Azure-compatible endpoint for lakehouse storage. Through this endpoint, you work with OneLake files using the same patterns and APIs as Azure Blob Storage or Azure Data Lake Storage (ADLS). With the C3 AI AzureFileSystem, you can mount OneLake and use it as a standard file system in the C3 Agentic AI Platform.
This page shows you how to connect a C3 AI application to Microsoft Fabric OneLake. You then use OneLake as an Azure-compatible file system to read and write files, list directories, and manage access.
Before you begin
Make sure you have the following:
- Access to a Microsoft Fabric workspace and at least one Lakehouse.
- A C3 AI environment with permissions to configure
FileSourceSystem. - An Azure AD app registration (service principal) if you plan to use client secret credentials.
Step 1: Create a Fabric workspace and Lakehouse
Go to Microsoft Fabric and sign in with your Microsoft account.
If you do not already have a workspace to connect to, select the New workspace tile. The workspace creation dialog opens.
Choose a Fabric-enabled workspace type:
- Fabric
- Fabric Trial
- Power BI Premium
Confirm workspace eligibility with your tenant administrator, if applicable. If you are not using a trial workspace, you may need an administrator to configure the workspace correctly and to review any billing implications.
Go to the workspace where you want to store files and open it.
Create a new Lakehouse if you do not have one. The Lakehouse stores files within your workspace.
Select + New item to create a new Lakehouse.
Enter a descriptive name for the Lakehouse that matches your project.
Select Create. The Lakehouse appears in your workspace, ready to store and manage files.
Step 2: Create a FileSourceSystem
In your application, create a FileSourceSystem for each Fabric Lakehouse you want to connect to.
Open your C3 AI application package and go to the directory where metadata definitions are stored.
Create a new
FileSourceSystemmetadata file similar to the following example:In your package, go to
/metadata/FileSourceSystem/.Create a file such as
OneLakeFileSource.json.
Add the following
FileSourceSystemconfiguration to the file:
{
   "name": "OneLakeFileSource",
   "rootUrlOverride": "azure://<WORKSPACE_NAME>/<LAKEHOUSE_NAME>.Lakehouse/Files/"

}
Specify the workspace and Lakehouse identifiers. Replace
<WORKSPACE_NAME>with the name of the workspace and<LAKEHOUSE_NAME>with the name of the Lakehouse.You can also use GUIDs instead of names, which helps when the workspace or Lakehouse names contain special characters. The browser URL shows the workspace and Lakehouse GUIDs when you view the Lakehouse.
Example URL:
https://app.fabric.microsoft.com/groups/<WORKSPACE_GUID>/lakehouses/<LAKEHOUSE_GUID>With GUIDs, your
rootUrlOverrideis:"azure://<WORKSPACE_GUID>/<LAKEHOUSE_GUID>/Files/"
Do not include .Lakehouse in the URL when you use GUIDs.
- Create a
FileSourceSystemspecifically for the Lakehouse you want to connect, to avoid configuration conflicts.
Step 3: Choose an authentication method
You can authenticate to OneLake with one of the following methods:
Client secret credentials: configure the following on the
AzureCredentialsobject for your source system:- Client ID
- Client secret
- Tenant ID
Workload identity (Azure clusters only): needs no client secret. Workload identity uses the service principal associated with the environment of your Azure Kubernetes Service (AKS) pod.
Use the same credentials or service principal for all Lakehouses in the same workspace, because they share the same access requirements.
Client secret credentials
To use client secret credentials, you need an application registration or service principal in Azure. The application registration or service principal must be in the same Azure tenant as the Fabric Lakehouse you intend to access. If none exists, create a new application registration with the following steps.
Go to your Microsoft Azure Portal and sign in.
In Azure Portal, go to App registrations > New registration.
Enter the name of the application and select Register.
Select the Overview tab on the left side of the panel.
Record the credentials of the application registration.
- Application (client) ID
- Directory (tenant) ID
On the left panel, go to Manage > Certificates & secrets > Client secrets.
Create a client secret if you do not already have one.
Select + New client secret, enter the description and expiration, and select Add.
Copy the secret value and store it in a secure location.
Go to Microsoft Fabric and select the workspace you created in Step 1: Create a Fabric workspace and Lakehouse.
Do not go to the created Lakehouse. You give access to the entire workspace, not just the Lakehouse.
Select Manage access in the top right corner.
Select Add people or groups and share the workspace with the name of your service principal or app registration.
Grant Viewer for read-only access, or any other role to allow write permissions. For roles and permissions, see Workspace roles in Lakehouse.
Set the credentials on the
FileSourceSystem:
fss = c3.FileSourceSystem.forName("OneLakeFileSource")
# This name should match the previously created FileSourceSystem
# To use client secret credentials, set the client ID, tenant ID, and client secret recorded earlier.

client_id = "..."
tenant_id = "..."
client_secret = "..."

# Create and set the credentials.
# To access OneLake, you must set the endpoint to "blob.fabric.microsoft.com", and you must set storageCredentials.accountName to "onelake"

creds = {
    "type": "AzureCredentials",
    "endpoint": "blob.fabric.microsoft.com",
    "activeDirectoryId": tenant_id,
    "accessKey": client_id,
    "secretKey": client_secret,
    "storageCredentials": {
        "accountName": "onelake"
    }
}

fss.setCredentials(creds)
Workload identity (Azure clusters)
If you run on an Azure cluster, you can use workload identity authentication, so you do not manage client secret credentials. This method needs the service principal in your AKS pod's environment variables to be in the same Azure tenant as the Fabric workspace. You identify that service principal to grant it access to the workspace. If you do not know the service principal, get it from your Operations team or use client secret credentials instead.
If you know the correct service principal, share the Fabric workspace with it as follows.
Go to Microsoft Fabric and sign in.
Go to the workspace you created in Step 1: Create a Fabric workspace and Lakehouse.
Do not go to the created Lakehouse. You give access to the entire workspace, not just the Lakehouse.
Select Manage access in the top right corner.
Select Add people or groups and share the workspace with the name of your service principal.
Grant the appropriate permissions according to Workspace roles in Lakehouse. For example, Viewer gives read-only access.
Set the credentials on the
FileSourceSystem:
fss = c3.FileSourceSystem.forName("OneLakeFileSource")
# This name should match the previously created FileSourceSystem # To use workload identity, you do not need to set any credentials specific to your service principal.
# You simply need to set the endpoint and storage credentials name to the correct value to ensure that we access OneLake.
# Create and set the credentials.
# To access OneLake, you must set the endpoint to "blob.fabric.microsoft.com", and you must set storageCredentials.accountName to "onelake"
creds = {
"type": "AzureCredentials",
"endpoint": "blob.fabric.microsoft.com",
"storageCredentials": {
"accountName": "onelake"
}
}
fss.setCredentials(creds) Step 4: Mount a OneLake path
Define a mount to restrict the connector to a specific directory. Create at least one mount per Lakehouse. Mount subfolders for finer control.
# In this case, you can set the mount to be the same as the rootUrlOverride.

workspace_name = "<WORKSPACE_NAME>"
lakehouse_name = "<LAKEHOUSE_NAME>"

# When setting the mount URL, if you want to access all files in the Lakehouse, you can remove the "myOneLakeRoot/" at the end; this is just an example of a restricted root directory to limit the scope of the connector's access
# The four parts that are necessary are the scheme ("azure://"), workspace name, Lakehouse name, and "Files" (this is the root of all files in your lakehouse, automatically created by Microsoft Fabric/OneLake)

mount_url = f"azure://{workspace_name}/{lakehouse_name}.Lakehouse/Files/myOneLakeRoot/"

# If you used GUIDs for your rootUrlOverride in the FileSourceSystem, you should do that here as well
# Get the Workspace and Lakehouse GUIDs from the URL in your browser address bar when viewing the Lakehouse
# For example, extract the IDs from a URL like this: "https://app.fabric.microsoft.com/groups/<WORKSPACE_GUID>/lakehouses/<LAKEHOUSE_GUID>"
# Uncomment if using GUIDs instead of names.
# We do not need the ".Lakehouse" in the URL when using GUIDs
# workspace_guid = "<WORKSPACE_GUID>"
# lakehouse_guid = "<LAKEHOUSE_GUID>"
# mount_url = f"azure://{workspace_guid}/{lakehouse_guid}/Files/myOneLakeRoot/"

c3.FileSystem.azure().setMount("oneLakeMount", mount_url) Step 5: Perform file operations
Most operations that AzureFileSystem supports are available. The examples in this step show the following operations:
- List files
- Write to a new file
- Read a file
- Write to a new file in a directory
- List files on a non-empty root
- List only the nested directory
- Delete a file
- List again to verify that the file is deleted
List files
Input
# List files on empty root:
c3.FileSystem.azure().listFiles(mount_url)
Output
{
  "type" : "ListFilesResult"
} Write to a new file
Input
# Write to new file:
f1 = c3.FileSystem.azure().makeFile(mount_url + "myTestFile1.txt")
f1.writeString("Test100")
Output
{
  "type" : "AzureFile",
  "url" : "azure://TestWorkspaceNT2/TestLakehouseNT2.Lakehouse/Files/myOneLakeRoot/myTestFile1.txt"
}
Read a file
Input
# Read a file
f1.readString()
Output
'Test100'
Write to a new file in a directory
Input
# Write to new file in a directory
f2 = c3.FileSystem.azure().makeFile(mount_url + "myDir/myTestFile2.txt")
f2.writeString("Test200")
f2.readString()
Output
'Test200'
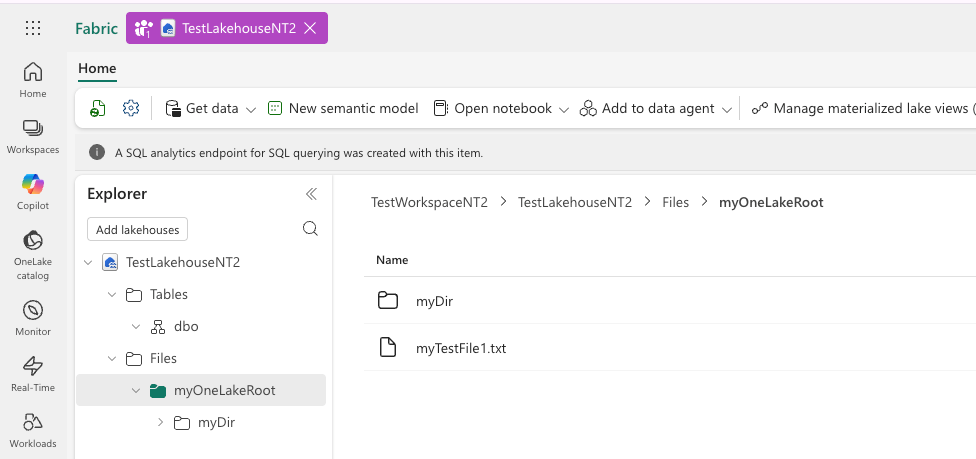 |
| File in the Lakehouse UI |
List files on a non-empty root
Input
# List files on non-empty root
c3.FileSystem.azure().listFiles(mount_url)
Output
{
  "type" : "ListFilesResult",
  "files" : [ {
    "contentLength" : 7,
    "eTag" : "0x8DE6B58FE6A2020",
    "lastModified" : "2026-02-13T23:38:30Z",
    "contentMD5" : "rldTlS99tLHVallC4IR2+Q==",
    "url" : "azure://TestWorkspaceNT2/TestLakehouseNT2.Lakehouse/Files/myOneLakeRoot/myDir/myTestFile2.txt"
  }, {
    "contentLength" : 7,
    "eTag" : "0x8DE6B58FD7464E8",
    "lastModified" : "2026-02-13T23:38:28Z",
    "contentMD5" : "8G5+mAGYETCGaaJNJno5XQ==",
    "url" : "azure://TestWorkspaceNT2/TestLakehouseNT2.Lakehouse/Files/myOneLakeRoot/myTestFile1.txt"
  } ]
} List only the nested directory
Listing only the nested directory shows one file.
Input
# Listing only the nested directory shows one file
c3.FileSystem.azure().listFiles(mount_url + "myDir/")
Output
{
  "type" : "ListFilesResult",
  "files" : [ {
    "contentLength" : 7,
    "eTag" : "0x8DE6B58FE6A2020",
    "lastModified" : "2026-02-13T23:38:30Z",
    "contentMD5" : "rldTlS99tLHVallC4IR2+Q==",
    "url" : "azure://TestWorkspaceNT2/TestLakehouseNT2.Lakehouse/Files/myOneLakeRoot/myDir/myTestFile2.txt"
  } ]
}Delete a file
Delete the first file that you wrote:
f1.delete()List again to verify that the file is deleted
Input
# List again. We see that the deleted file is no longer there
c3.FileSystem.azure().listFiles(mount_url)
Output
{
  "type" : "ListFilesResult",
  "files" : [ {
    "contentLength" : 7,
    "eTag" : "0x8DE6B58FE6A2020",
    "lastModified" : "2026-02-13T23:38:30Z",
    "contentMD5" : "rldTlS99tLHVallC4IR2+Q==",
    "url" : "azure://TestWorkspaceNT2/TestLakehouseNT2.Lakehouse/Files/myOneLakeRoot/myDir/myTestFile2.txt"
  } ]
}Access raw Delta Lake files in a Lakehouse (advanced)
Work with the Lakehouse through the Files folder instead of the raw Delta Lake storage. Keep direct access to the Tables directory for advanced scenarios where your application manages Delta Lake file formats itself.
C3 AI applications can optionally access the raw Delta Lake table files stored in a Lakehouse. Use this capability only for advanced cases that need direct access to the raw storage layer.
Mount the Tables directory
Besides the Files directory of a Lakehouse, you can also mount the Tables directory. Applications can then run standard file system operations on the raw Delta Lake files, like the operations on the Files directory in Step 5.
Example:
tables_mount_url = f"azure://{workspace_name}/{lakehouse_name}.Lakehouse/Tables/"

c3.FileSystem.azure().setMount("OneLakeTablesMount", tables_mount_url)
After you mount the directory, applications work with it through standard c3.FileSystem operations.
Important considerations
The Tables directory holds the storage representation of Delta Lake tables. Each table consists of multiple files, including:
- Parquet data files
- Transaction log metadata (for example, Delta Lake log files)
A single logical table may span many data and metadata files, so read these files according to the Delta Lake specification.
For this reason:
- Do not use the
Tablesdirectory for general work. - Access these files only from applications designed to parse and manage Delta Lake table structures correctly.