Share Data Lakehouse Tables Across Applications
The C3 AI Data Lakehouse supports two sharing patterns between a producer and a consumer. The producer is the application that owns the tables. The consumer is the application that receives access to them.
The request-and-approve workflow gives a consumer a share of a table, or a download of one snapshot, after a reviewer approves. You can run the entire flow (submit, approve, download) in C3 AI Studio, and manage table-level access control lists (ACLs) with fine-grained roles.
The external-application catalog gives the consumer a long-lived delegating view of the producer's tables: listing, metadata reads, and table creation forward to the producer, and deleteTable is not supported on this catalog. You set up the catalog from a notebook and use it from then on through the same Studio user interface.
In C3 AI Studio: Request and approve a share or download
Use the share or download request workflow in these cases:
- The consumer needs a specific snapshot, not a live view.
- You need a compliance audit trail.
- One team wants to receive the dataset as a file.
Roles
C3.DisclosureRequestor: A role in the consumer application that can file share or download requests.C3.DisclosureReviewer: A role in the producer application that approves or rejects requests.
A user without one of these roles cannot see the share and download request options.
File a share or download request
A user with the C3.DisclosureRequestor role files the request from the table's row actions menu (...) on the Tables tab.
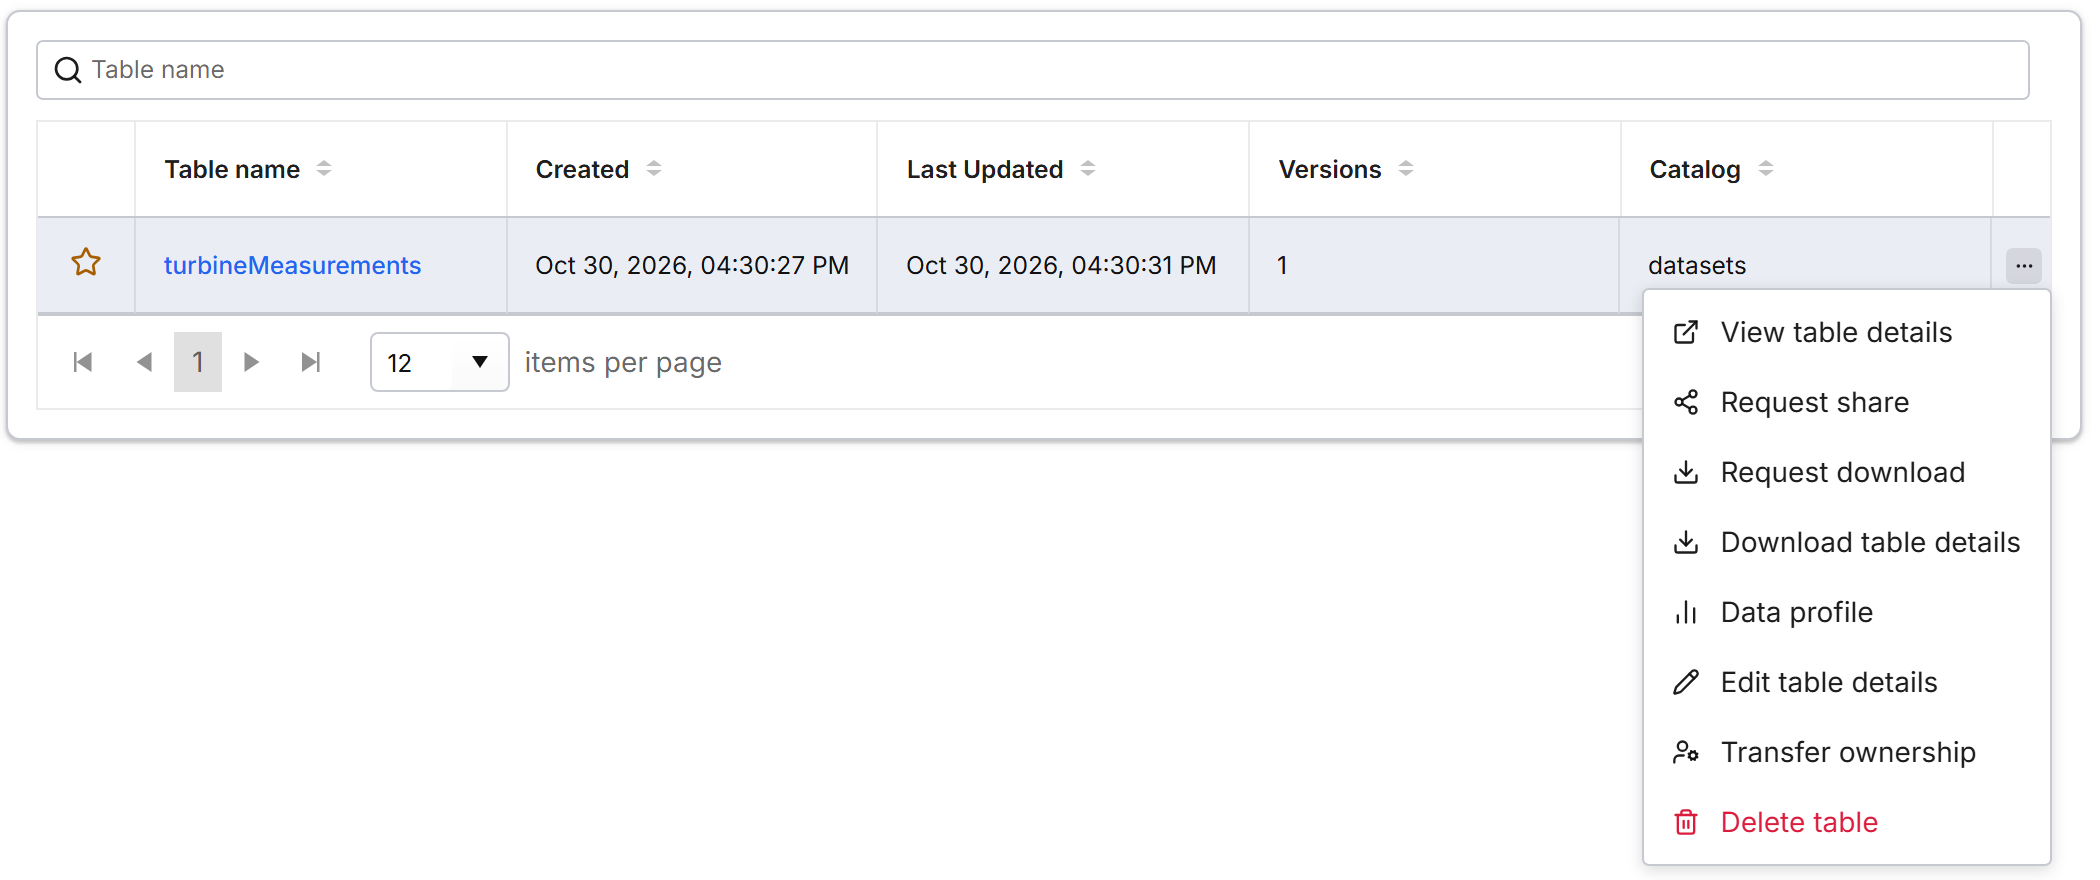 |
| File a share or download request |
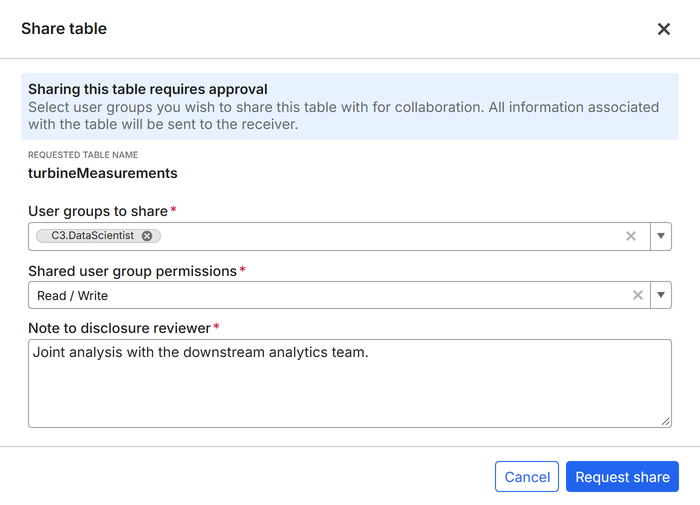 |
| Request share access to a table |
After a reviewer approves a download request, the consumer downloads the file from the Downloads page in C3 AI Studio. See C3 AI Studio Data Lakehouse Downloads for the consumer side of the flow.
Approve a share or download request
A user with the C3.DisclosureReviewer role reviews requests on the Requests page in C3 AI Studio:
- Open the Share requests tab or the Download requests tab.
- Select Review on a pending request. The dialog shows the table, the requestor, the request date, and the Note to reviewer.
- Select Approve or Reject.
After a share request is approved, the consumer finds the table on the Tables tab under Shared with me.
From a notebook (optional)
If you prefer to file or approve a request from a notebook:
# Run as a user with the C3.DisclosureRequestor role
catalog = c3.DataLake.Catalog.forName(c3.DataLake.Catalog.DEFAULT_CATALOG)
spec = c3.DataLake.Catalog.TableSpec.make()
table = catalog.table("turbineMeasurements", spec)

req = c3.DataLake.Table.ShareRequest.createRequest(
    table,
    c3.DataLake.Table.ShareRequest.CreateRequestSpec.make({
        "description": "Joint analysis with Atlas Power downstream team.",
    }),
)
A share request grants ongoing read access on the table; it does not bind to a specific snapshot. Use a DownloadRequest if you need a point-in-time capture instead.
# Run as a user with the C3.DisclosureReviewer role
req = c3.DataLake.Table.ShareRequest.forId("<request id>")
req.approveRequest()
To reject:
req.rejectRequest()The download request follows a similar pattern, but takes a specific snapshot:
# Run as a user with the C3.DisclosureRequestor role
snapshot = table.snapshots[0]

req = c3.DataLake.Table.DownloadRequest.createRequest(
    table,
    snapshot,
    c3.DataLake.Table.DownloadRequest.CreateRequestSpec.make({
        "description": "Q1 retrospective dataset.",
    }),
)
After the reviewer approves, the consumer downloads the file from the Downloads page in C3 AI Studio.
From a notebook: External-application catalog
The external-application catalog gives a consumer application a long-lived delegating view of the producer application's catalog. Listing tables, reading table metadata, and createTable run in the producer application. deleteTable is not supported on this catalog. Choose this catalog when the consumer needs always-current access without filing a request for every snapshot. You set up the catalog once from a notebook. After that, the catalog is visible from the Catalogs tab in C3 AI Studio and queryable from the SQL Editor tab.
Producer setup
The producer application grants the consumer application access by application identity. The producer does not need to know the consumer's users. As a user with C3.AppAdmin in the producer application, run:
# Run in the producer application
c3.App.forId("<producer app ID>").allowAccess("<consumer app ID>", ["<role ID>"], False)- Replace
<role ID>with the role that the consumer application gets in the producer application. The role must allow reading the producer's Data Lakehouse catalog and tables. - The call fails if the consumer already has access. To change the roles of an existing grant, use
App.addRolesorApp.revokeRoles. To remove the grant, callrevokeAccess("<consumer app ID>").
If the producer has not granted access, creating the catalog in the consumer application fails with App Identity is not configured on <producer app ID> for current app!.
Consumer setup
In the consumer application, register an external-application catalog that points at the producer:
conf = (
    c3.DataLake.Catalog.Config.ExternalApp.builder()
    .appId("atlas-power-prod")
    .catalogName(c3.DataLake.Catalog.DEFAULT_CATALOG)
    .name("upstream")
    .build()
)
upstream = c3.DataLake.createCatalog("upstream", conf)
After the catalog is registered, every consumer-side user can use it through the same Studio user interface as any other catalog:
- The catalog appears on the Catalogs tab as
DataLake.Catalog.ExternalApp. - The catalog is selectable from the SQL Editor tab's Catalog dropdown.
To list and read tables from a notebook:
upstream.tables(c3.DataLake.Catalog.TableSpec.make())
table = upstream.table(
    "turbineMeasurements",
    c3.DataLake.Catalog.TableSpec.make().withNamespace("dfl"),
)Choose between the two patterns
| Need | Pattern |
|---|---|
| Live, always-current read access to a producer's tables | External-application catalog |
| One-off transfer of a specific snapshot | Share or download request |
| Compliance audit trail for who got what data and when | Share or download request |
| No coupling between consumer and producer schedules | External-application catalog |
ACL privileges
The platform seeds privileges that control Lakehouse-related access, including table-level ACL with fine-grained roles. The managed Iceberg table privileges come as three distinct IDs:
DataLakeTableManagedIcebergOwnerPrivilege: Identifies the owner of a managed Iceberg table.DataLakeTableManagedIcebergSharedReadOnlyGroupsPrivilege: Grants read-only access to a managed Iceberg table for a group.DataLakeTableManagedIcebergSharedUpdateRemoveGroupsPrivilege: Grants update and remove access to a managed Iceberg table for a group.
For Spark workload visibility:
SparkExecutionAclPrivilege: Controls who can see Spark Executions.
Grant these privileges to roles in your application's package metadata. The C3.DisclosureRequestor role grants read access to Lakehouse catalogs and managed Iceberg tables, and the C3.DataScientist role includes it.