Upload Files
The C3 Agentic AI Platform provides file uploads through C3 AI Studio, the import API, or the file API. The file API uploads files to any connected file system. This page also covers moving files between remote file systems and an example workflow for loading data.
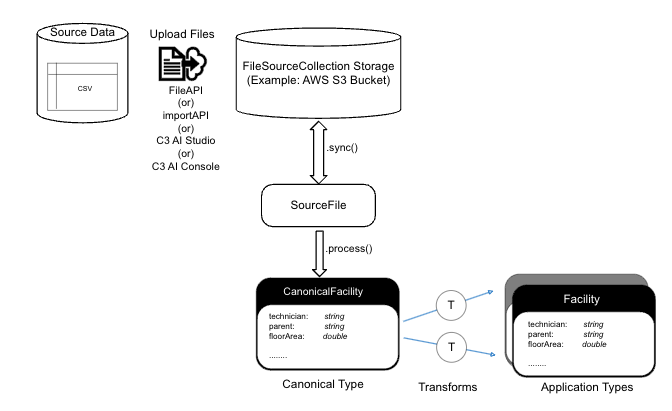
The following data upload flow diagram shows how data from multiple sources moves through upload, synchronization, processing, and transformation into a unified view.
Files are truncated when they exceed 2GB due to REST API limitations. You may need to split large files and upload smaller files individually.
Identify source data
Locate the raw data files you want to integrate, such as CSV, JSON, Parquet, or AVRO files. Find out where the data comes from: an external database, a partner, or an IoT device. Source data is the raw or original data that you upload or integrate into the system. Source data can be structured, semi-structured, or unstructured.
Upload data to FileSourceCollection storage
FileSourceCollection storage is the file location that holds uploaded files before the data integration pipeline processes or transforms them. FileSourceCollection storage keeps files accessible for synchronization and the later steps of the workflow. The FileSourceCollection storage is often a cloud bucket or blob store (such as Amazon S3, Azure Blob Store, or GCS Bucket).
Use any of the following methods to upload data to the FileSourceCollection storage.
- FileAPI: Use the C3 AI
fileAPI to upload the source data files into a specific file collection within the platform. ThefileAPI only stores the file in the FileSourceCollection storage, so you must runsync()andprocess()yourself later. - importAPI: Use the
importAPI option to upload the file and to automatically trigger both the synchronization (sync()) and processing (process()) of the file. Processing ingests the data and imports it into the Application Types. - Data Fusion in C3 AI Studio: Alternatively, you can upload files to a File Source Collection in Data Fusion. See Upload files in C3 AI Studio.
- C3 AI Console: In the C3 AI Console, select Tools, then select Load File. The Load Local File dialog opens, where you choose a file and its destination.
- Cloud Native Tools: Use other cloud tooling to upload files to the underlying bucket or blob store.
Use the File API and C3 AI Console to upload files that test the DI pipeline, or to store files without immediate processing. These operations require additional steps to transform the data.
Synchronize the data as a SourceFile
A SourceFile is a Type in the C3 Agentic AI Platform that is the record of an underlying file on the file system. This record tracks metadata on the file size, upload date, and file location, and also enables lineage to any downstream processing. Synchronizing makes the files available for processing and transformation in the data integration workflow. Without synchronization, the stored files stay disconnected from the data model, and you cannot process them.
After the data is uploaded to the FileSourceCollection storage, there are two methods to synchronize the file. The first option is to open Data Fusion in C3 AI Studio. On the Data Integration tab, select ... on the File Source Collection node, then select Sync source files.
The second option is to use the SourceFile.syncAll() API to synchronize the uploaded data in the C3 Agentic AI Platform as shown in this example.
// Get the inboxUrl for the FileSourceCollection
var fileUrl = FileSourceCollection.forName('<FSC_NAME>').inboxUrl();
SourceFile.syncAll(fileUrl, {process: false});
The second parameter in syncAll() is a DataIntegSpec, which controls synchronization options, such as whether to process the file immediately or delay the processing.
Syncing the file to create a SourceFile record is entirely separate from processing the data. With this design, you can sync all files at a given FileSourceCollection storage location and process only a subset of them.
Process data into a structured Canonical Type
A Canonical Type defines a standardized format to represent source data in a consistent, unified way within the system. A Canonical Type serves as an intermediate between raw data and the application data model, allowing data from various sources to be processed and integrated. By converting raw source data into Canonical Types, the system keeps data consistent and makes later integration into application-specific types easier.
To perform initial data processing, use SourceFile.process(), SourceFile.processBatch(), or SourceFile.processAll() APIs as shown in the following example.
Example:
// .process() for one SourceFile
var sourceFileId = '<ID of SourceFile in C3 AI>';
SourceFile.forId(sourceFileId).process();

// .processBatch() for a group of SourceFiles
var sourceFiles = SourceFile.fetch({filter: "<some_filter_statement>"}).objs;
SourceFile.processBatch(sourceFiles);

// .processAll() for processing all SourceFiles according to a filter
var spec = DataIntegSpec.make({filter: "<some_filter_statement>"});
SourceFile.processAll(spec);
Processing validates the raw data in the SourceFile and transforms it into a structured Canonical Type. The downstream data pipeline then processes the canonical data immediately. This step standardizes, cleans, and prepares the data for further use or transformation within the system.
Example from the diagram:
In the diagram, the Canonical Type is represented by the example CanonicalFacility. CanonicalFacility includes attributes like:
- technician: string (a field representing a technician's name)
- parent: string (a field referring to a parent facility or entity)
- floorArea: double (representing the floor area as a numerical value)
This canonical representation standardizes the data, regardless of how it was originally provided (for example, from different source files or databases).
Transform data
The transformation process involves converting raw source data into a canonical format by applying business rules, data cleaning, or reformatting. This canonical data is then mapped into application-specific formats to meet the needs of different systems. After initiating the processing of data from the previous step, there is no need to manually start the transformation step. Processing and transformation happen as one process.
The two transform arrows in the diagram represent the conversion of canonical data, such as CanonicalFacility, into multiple application types. These arrows signify that the standardized data can be adapted in parallel for various use cases. For example, one arrow may map CanonicalFacility to a detailed facility structure. The other might map CanonicalFacility to a summary type for reporting or analytics purposes.
Example from the diagram:
In the diagram, the CanonicalFacility has the attributes technician, parent, and floorArea. The two transform arrows map these fields into different application types:
- First Transform arrow: Maps CanonicalFacility into an Application Type used by the operational system for managing facility operations.
- Second Transform arrow: Maps CanonicalFacility into another Application Type used for reporting or analytics, focusing on key performance indicators (KPIs) like total floor area or technician details.
Upload files in C3 AI Studio
You can upload .csv files to an application in C3 AI Studio. First, open Data Fusion in your application:
- Select the Apps icon to find your application.
- Select your application.
- Expand the navigation pane to reveal the AI Studio tabs.
- Expand DATA, then select Data Fusion.
You are now ready to upload files through C3 AI Studio.
Upload files to a File Source Collection
You can upload one file or several files at once. The files go to the folder of a FileSourceCollection.
On the Data Integration tab, select the File Source Collection node for your files. The Set Source File Path dialog opens and lists the files in the collection's folder.
Check that File source collection shows the collection you want.
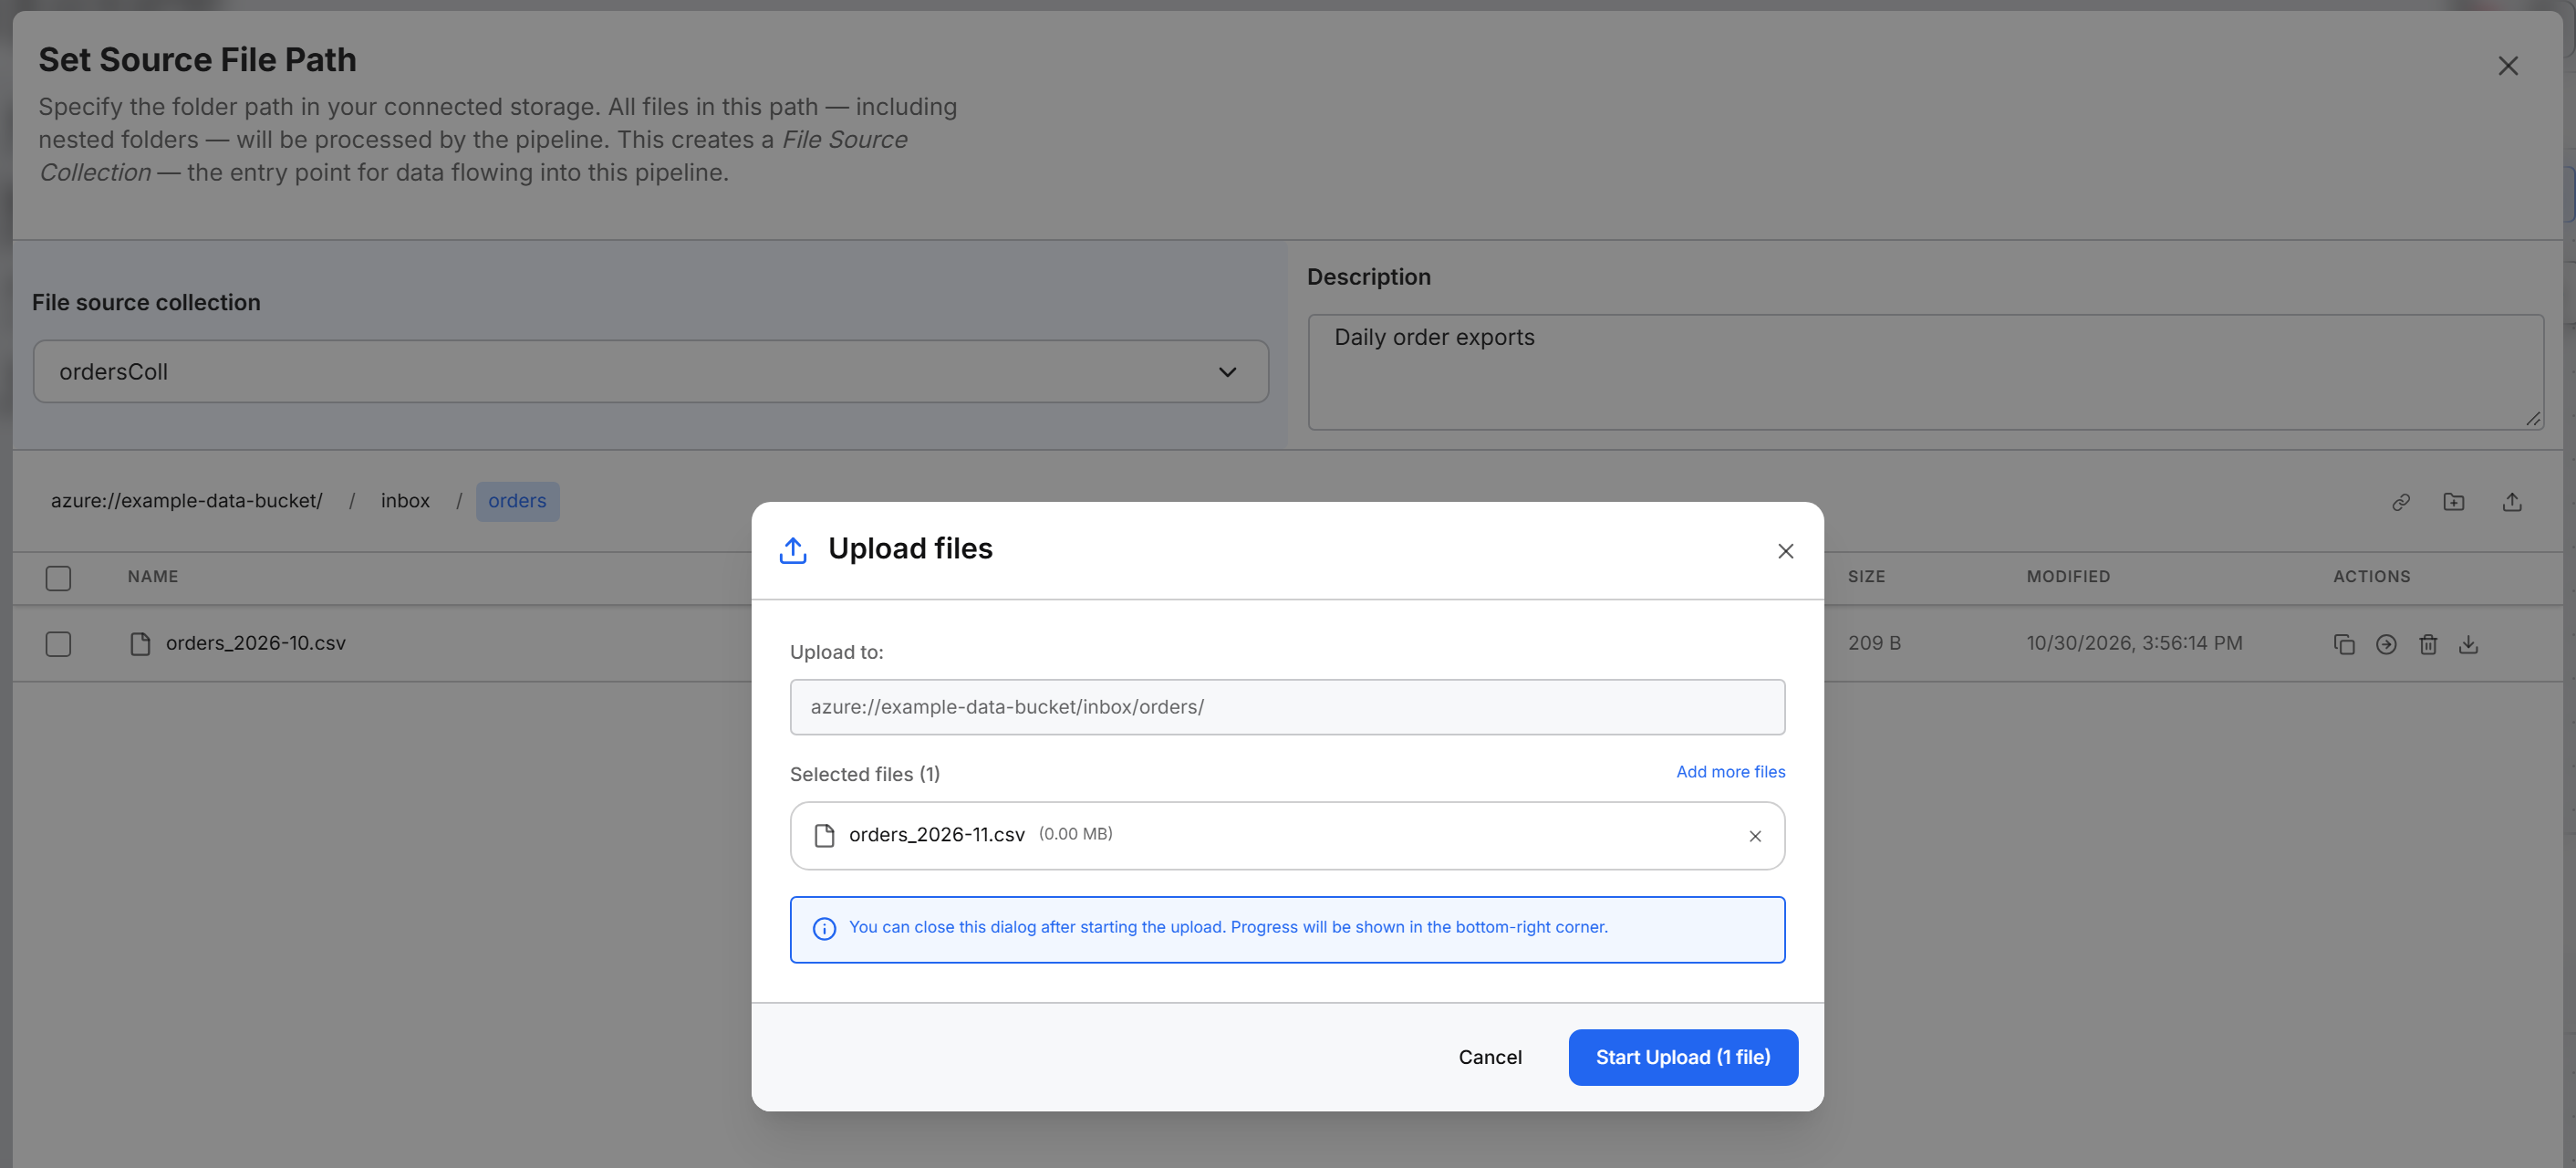
Select the Upload files icon above the file list.
Select Click to select files to choose the files you want to upload. Alternatively, drag the files from another window into the dialog.
Select Start Upload.
The uploaded file appears in the list. Select the file name to preview its contents.
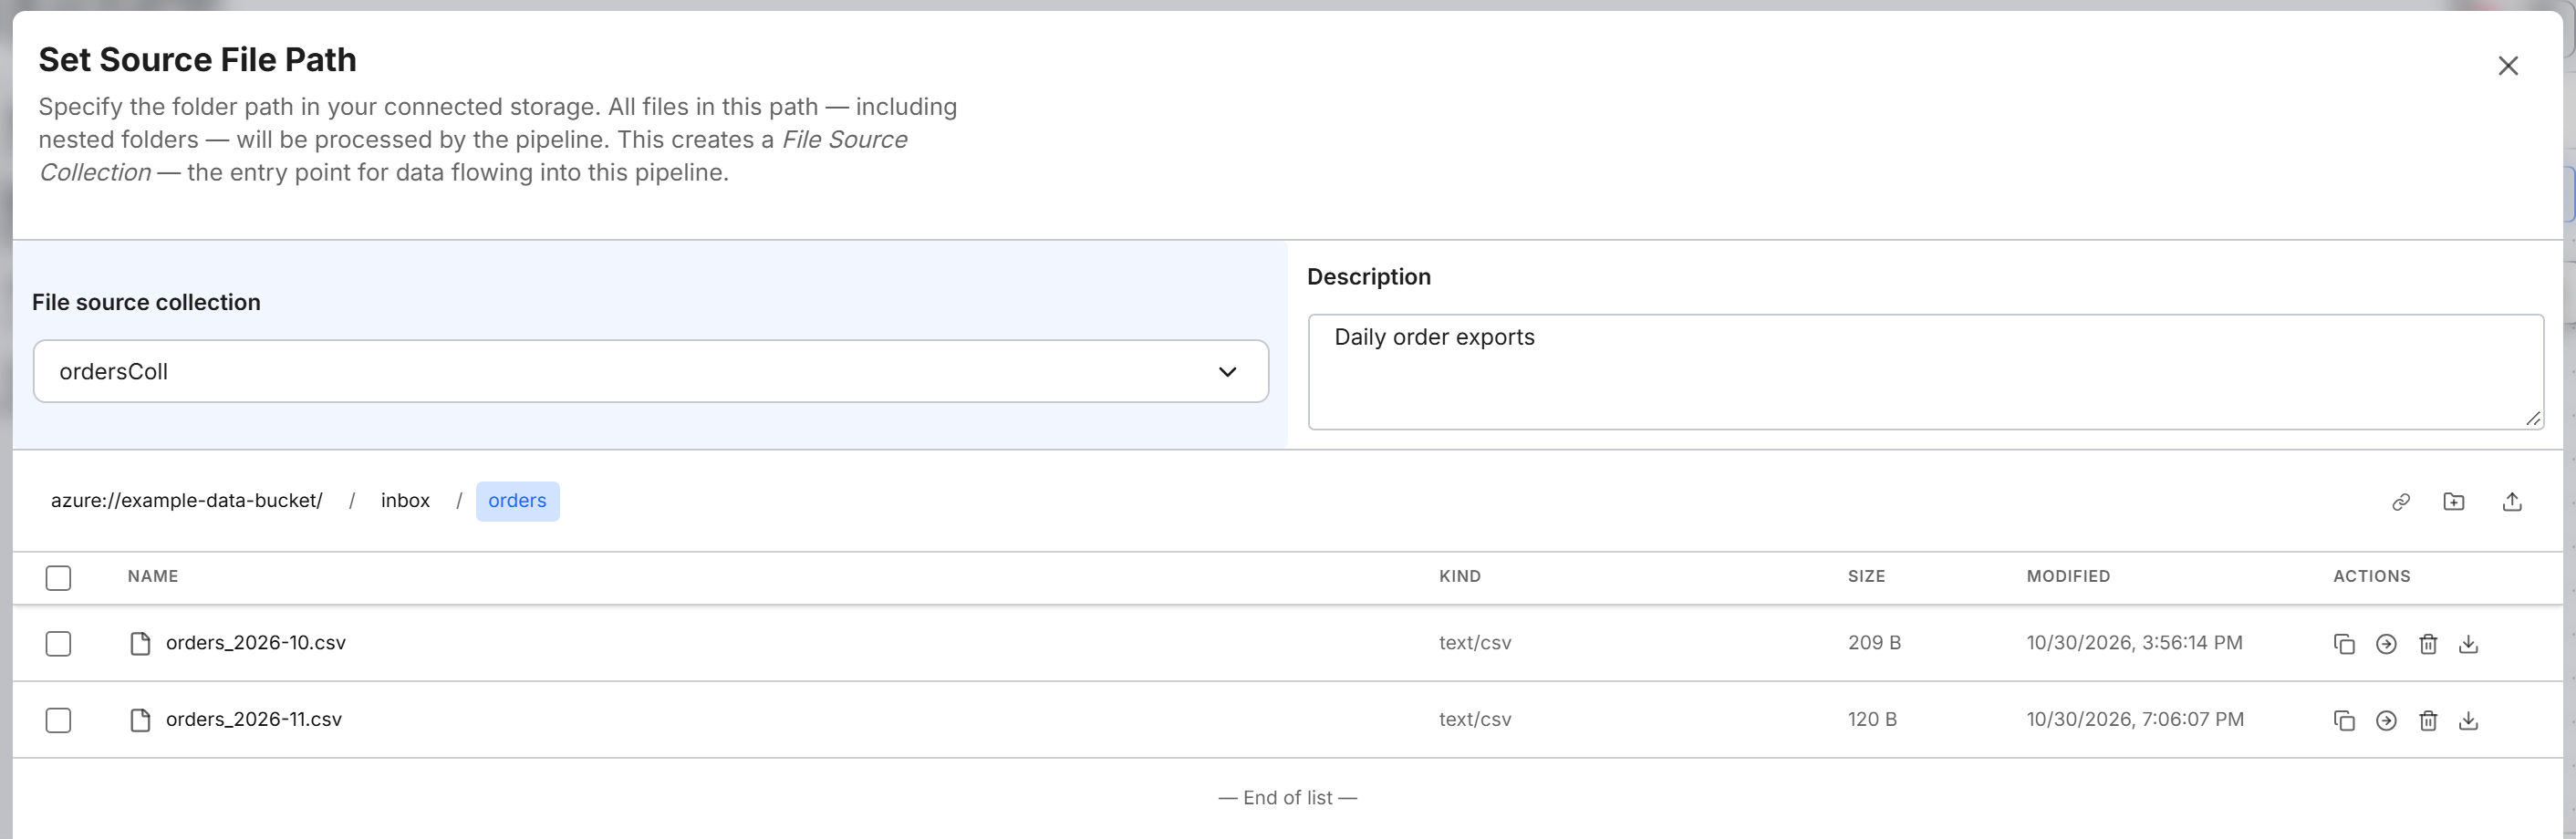
To sync the uploaded files, close the dialog, select ... on the File Source Collection node, then select Sync source files.
Upload local files with the File API
The C3 Agentic AI Platform provides a file API that lets you upload a local file to any connected file system. The Curl Type provides utility functions to prepare a cURL request. You can run a cURL request from your local machine to call C3 Agentic AI Platform REST APIs.
To prepare a cURL request that uploads a local file to a remote file system, run the following:
// Example of file location on the default file system
var contentLocation = FileSystem.mounts().get('/') + 'path/to/file.csv';
var contentType = "text/csv"; // e.g. "text/csv"
var contentEncoding = "UTF-8"; // usually "UTF-8"
var localFilePath = "path/to/local/file.csv"; // e.g. "/Users/someuser/Documents/my_file.csv"
var authKind = AuthenticationKind.C3;

Curl.file({
  contentLocation: contentLocation,
  contentType: contentType,
  contentEncoding: contentEncoding,
  localFilePath: localFilePath,
  dataBinary: true,
  authenticationKind: authKind,
  authenticationToken: User.myUser().sessionToken().signedToken
});
The call returns a cURL command on one line, like the following example:
curl -H "Authorization: c3auth <token_value>" -H "Content-Type: <content_type>" -H "Content-Encoding: <content_encoding>" -X PUT --data-binary @"<local_file_path>" <application_url>/file/<content_location> --ssl -vTo send the file to the remote file system, open a new Terminal session and run the copied cURL command.
A 200 status means that the upload to the remote file system succeeded. To confirm that the file is on the remote file system, run FileSystem.listFiles(contentLocation).
FileSystem.listFiles() lists files in the default file system. If you uploaded your files to a different file system, such as S3 or Azure Blob, use the matching file system, for example FileSystem.s3().listFiles() or FileSystem.azure().listFiles().
The following file formats are supported for uploading:
CSV
JSON
XML
Parquet
Avro
Error status codes
If you do not receive a 200 status from the cURL request, the error status code can help you debug the issue:
302: Redirect to the IdP, probably because the authorization header was not set correctly or is invalid.400: Bad request, generally because the destination path on the remote file system was not accessible.404: Requested endpoint not found, most likely because of a typo on the path to the file API after the host URL (should be/<env>/<app>/file).415: Unsupported media type, which means that the local file did not have a supported file format.500: Internal server error, which means that the server is unavailable to process the request.
If no HTTP response is received, the host address was not valid.
Move files between remote file systems
The FileSystem methods let you migrate data from one connected file system to another. The Type System abstraction layer makes the migration possible across clouds.
The following example copies the contents of the Azure file system's default mount to an S3 bucket connected to the C3 Agentic AI Platform:
var destinationPath = "<destination_file_system_path>";

var sourcePath = FileSystem.azure().urlFromMount() + "jupyter/";
FileSystem.azure().copyFiles(sourcePath, destinationPath);Example workflow for loading data
The following end-to-end workflow loads data to an environment. The workflow includes verification steps to make sure the files loaded to the correct location and are synchronized with the server.
These steps assume that you already configured the FileSourceCollection for the file source system. For more information, see Ingest Files from Amazon S3 Programmatically.
If you load historical data, make sure to disable async processing before performing data loads by running InvalidationConfig.inst().setConfigValue('upsertAsyncProcessingDisabled', true, ConfigOverride.APP).
To load data in an environment, do the following:
Set the URL for incoming files. Modify the
inboxUrlOverridevalue in the following example code snippet and run it in the C3 AI Console of your application.JavaScriptFileSourceCollection.forName("<sourceName>").config().setConfigValue("inboxUrlOverride","<folder-path>/<sourceName>");Use cURL to retrieve the files from a specified source and transfer them to your environment using either the File Type or Import Type. The cURL command sends files from your local system into the designated environment, for example to test the data pipeline locally on your single node environment.
File: Uploads the file to the path specified. TheFileType is the recommended approach for uploading files onto the C3 AI File System. See the following example code snippet.Command Linecurl -vv -L -H "Content-Type: text/csv" -H "Authorization: c3auth <auth_token>" \ -X PUT --data-binary @<filename>.csv <cluster-name>/<env_name>/\ <app-name>/file/<folder-path>/<sourceName>/<filename>.csvThe path after
/file/must match theinboxUrlOverridevalue you set in step 1. If that value is a URL with a scheme, such ass3://, URL-encode it in the path.Import: Loads and processes the file for the canonical specified. UseImportto load ad hoc data or to test data loads. See the following example code snippet.Command Linecurl -vv -L -H "Content-Type: text/csv" -H "Authorization: c3auth <auth_token>" \ -X PUT --data-binary @<filename>.csv <cluster-name>/<env_name>/<app-name>/\ import/8/<CanonicalName>/<filename>.csv
Verify the files are accurately copied to the intended location in the environment by running the following example code snippet.
JavaScriptvar url=FileSourceCollection.forName("<source_name>").inboxUrl() c3Grid(FileSystem.listFiles(url).files)Ensure the metadata associated with the files is synchronized and updated with the server. This synchronization process aligns the file metadata from the mount point with the server. See the following example code snippet.
This step lets the C3 Agentic AI Platform identify the file copied to the inbox URL and the mount point before the ingestion pipeline begins.
JavaScriptSourceFile.syncAll(FileSourceCollection.forName("<source_name>").inboxUrl());