Understand Unstructured Data Integration Pipelines
You have documents, such as PDFs, Word files, or slide decks, and you want an application to search them or answer questions from them. An Unstructured Data Integration (UDI) pipeline in C3 AI Data Fusion turns those documents into searchable passages that semantic search and retrieval-augmented generation (RAG) can use. Use this page to decide whether UDI fits your data and which choices to make before you build a pipeline.
Choose UDI or Structured Data Integration
Data Fusion offers two ways to bring data into an application. Choose by what your data looks like and what you want to do with it:
- Choose UDI when you want to search the content of documents or extract fields from them with a large language model (LLM). Supported documents include PDFs, Word and PowerPoint files, spreadsheets, HTML, Markdown, plain text, and images.
- Choose Structured Data Integration (SDI) when your data is rows with a fixed schema and you want column transforms, Change Data Capture (CDC), or incremental loads. Examples are a database table, a CSV, JSON, or Parquet file, and a streaming topic.
A spreadsheet fits both. Use UDI to search the content of a spreadsheet, and use SDI to load its rows into records in your application.
How a UDI pipeline processes a document
A UDI pipeline runs as a chain of nodes on the Data Fusion canvas, which you open from Data > Data Fusion in C3 AI Studio. Each node handles one stage of the work:
- Source collection: The set of files the pipeline processes, which is every file under one folder of a file source system, nested folders included.
- Chunker: Parses each document into text, images, and tables, then splits the content into chunks. A chunk is a piece of a document small enough to search on its own.
- Metadata Tagger (optional): Uses an LLM to tag each document with values from categories you define, such as a document type. The Metadata Tagger reads text sampled from the document and applies the tags to the whole document.
- Entity Extractor (optional): Uses an LLM to pull structured fields, such as a company name or a date, out of the document text and into records.
- Load (added with the Entity Extractor): Writes the extracted records to your application data model or to files in an external destination.
- Embedder: Computes an embedding for each chunk and stores it in a vector store. An embedding is a list of numbers that represents the meaning of a chunk, so search can find passages with similar meaning. A vector store holds each chunk with its embedding, and each stored chunk is a passage.
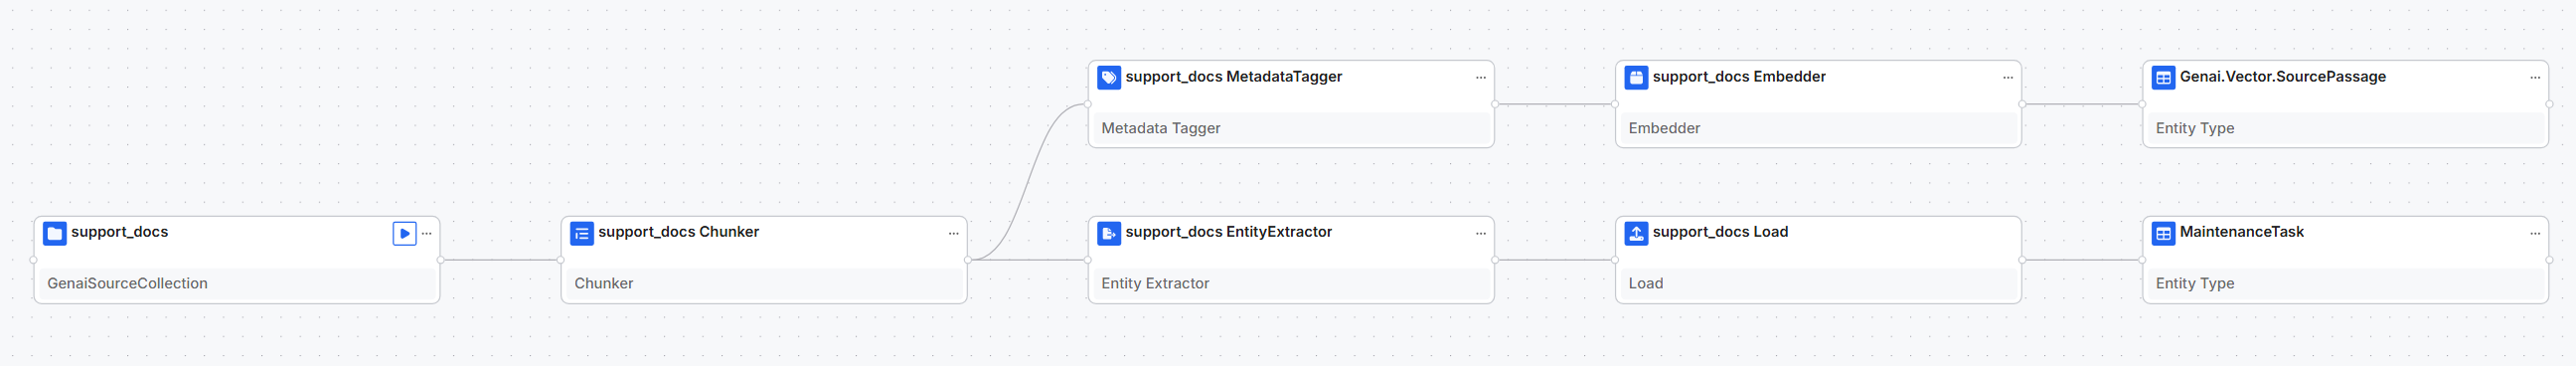
The Retriever ID names the vector store that the Embedder writes to and that search reads from. When a pipeline has a Metadata Tagger, the Chunker, the Metadata Tagger, and the Embedder run in series, so the tags exist before the Embedder runs. The Entity Extractor and its Load node form a separate branch from the Chunker.
For how the nodes connect on the canvas and what each node creates, see Unstructured Data Pipeline Architecture.
Choose Canonical or an external file source
A UDI pipeline reads from a file source system. The supported file sources are the built-in Canonical source system, Amazon S3, Azure Blob Storage, Google Cloud Storage, OneDrive or SharePoint, and Google Drive:
- Choose the built-in
Canonicalsource system when you want to upload files yourself through the Data Fusion UI.Canonicalstores files in the application's own file storage, so you need no external account or credentials. - Choose an external file source when your documents already live in cloud storage or a document library and should stay there. You connect to the external file source with the credentials that the provider requires.
When you create a source collection, you choose its Processing Engine. With Mew3, the default, the engine parses PDFs with the Chunker settings you choose. Other formats use the built-in parser for their format with its default settings. Doc AI is available only when the Doc AI service is deployed in your environment. A Doc AI collection sends its files to that service, which parses, chunks, and indexes them. The source file system must support presigned URLs, because a file without one is marked failed. The canvas then shows a Strategy node in place of the Chunker and the nodes after it. You can't change the engine after you create the collection.
For both routes, see Create an Unstructured Source Collection.
Choose how the Chunker parses documents
The Chunker offers four parsing presets, and the default is Pure VLM. Choose the preset that matches the content your documents carry:
- Pure VLM: Parses each page end to end with a vision language model (VLM).
- Balanced: General-purpose parsing for mixed content. Choose this preset for documents that mix text, images, and tables.
- Text focused: Parsing for text-heavy documents. Choose this preset for documents that are mostly text, such as reports or articles.
- Table focused: Spends extra effort on tables at a higher token cost. Choose this preset when losing table structure would lose information you need to retrieve.
For the settings each preset exposes, see Configure the Chunker.
Choose the optional nodes
After you save the Chunker, the canvas shows placeholders for the Entity Extractor, the Metadata Tagger, and the Embedder. A placeholder is a node for a step you have not configured yet. Decide which optional nodes to configure:
- Add a Metadata Tagger when you want each document labeled with properties such as type or topic. Each tag category is Open, where the LLM proposes values, or Closed, where the LLM picks from a list you define.
- Add an Entity Extractor when you want structured records, such as one record per contract with its parties and dates, alongside the searchable passages.
- Leave both out when you need only search over the document text.
For each node, see Configure Metadata Tagging and Configure Entity Extraction.
Choose the embedding model and the extracted-data destination
The Embedder's Embedding Model list shows the embedding model clients configured for your application in Model Hub > Clients. The list and its default vary by environment. Choose the model you plan to keep: changing the embedding model later means re-embedding every indexed document.
The Retriever ID field is prefilled with an existing ID, such as default-pg. Pipelines with the same Retriever ID share one vector store, and search returns passages from all of them. Keep the prefilled ID to add your passages to that store, or enter your own ID to keep a pipeline's passages separate. For details, see Configure the Embedder.
When you add an Entity Extractor, its Load node offers two destinations:
- Choose Load to Application Data Model when your application reads the extracted entities as records. Saving the Load node creates the target entity Type, the definition of the records that hold the extracted fields.
- Choose Load to External Source when another system consumes the extracted entities as files.
For both destinations, see Configure the Load Destination.
Track a pipeline run
You start each run with the Execute pipeline button on the source collection node. To check progress, open the source collection node's menu (the three-dot button) and select View run status. The dialog shows how many files are at each pipeline stage. Each run also starts jobs that you can follow in C3 AI Studio:
- The sync job, which lists the collection's files, appears on Monitoring > Jobs > Batch.
- The chunking job, which parses and chunks the files, appears on Monitoring > Jobs > MapReduce.
For each status and what to do when a file fails, see Monitor Pipeline Execution.