Configure SQL Sources
Your data lives in a relational database or data warehouse, such as PostgreSQL, Snowflake, or Microsoft SQL Server. A SQL source connects the C3 Agentic AI Platform to that database through Java Database Connectivity (JDBC). You can query the table in place from your application, or copy its rows into your application with a data integration pipeline. You choose a mode for each table, then a connector for your database in Data Fusion.
When to use a SQL source
Use a SQL source when:
- The data lives in a relational warehouse or an online transaction processing (OLTP) database, such as PostgreSQL, Snowflake, Microsoft SQL Server, or BigQuery.
- The application can reach the database over the network through JDBC.
- You want to read the table without copying it, or copy new and changed rows into entity Types with change data capture (CDC). Entity Types are the Types whose records your application stores in its database.
If the data arrives as files in storage, use a file source. If the data arrives as messages on a message broker, use a streaming source. For those sources, see Configure File Sources and Configure Streaming Sources.
Parts of a SQL source
A SQL source has three parts:
- Source system: the database connection. The SqlSourceSystem Type represents the source system and holds the connection details and the credentials. In Data Fusion, a source system is the connector you add with Add Data Source.
- Source collection: one table in that database. The SqlSourceCollection Type represents a source collection. In Data Fusion, a source collection appears as a SQL Source Collection node.
- Source Type: a user-defined Type with one field for each column of the table, so it describes one row. When the platform infers this Type from a table, the Type mixes in
ExternalandSource. In Data Fusion, the Source Type appears as an External Entity Type node.
The External mixin means that the platform does not store the Type's rows in the application's database; the rows stay in the source table. The mode is a setting on the source collection, so the same Source Type serves both modes.
The source system authenticates with database credentials: the server endpoint, port, datastore type (the kind of database), database name, schema name, username, and password. Some connectors offer other sign-in methods. You enter the credentials in the connector wizard in Data Fusion, or set them with setCredentials on the source system. The platform stores the credentials for the application. For the methods each connector supports, see Authenticate Database Sources.
Choose a mode: Virtual Table or Load Data
Each SQL source collection runs in one of two modes. In Data Fusion, select Edit properties on the menu of the collection's node, then choose the mode in the Edit Properties dialog. Virtual Table is the default.
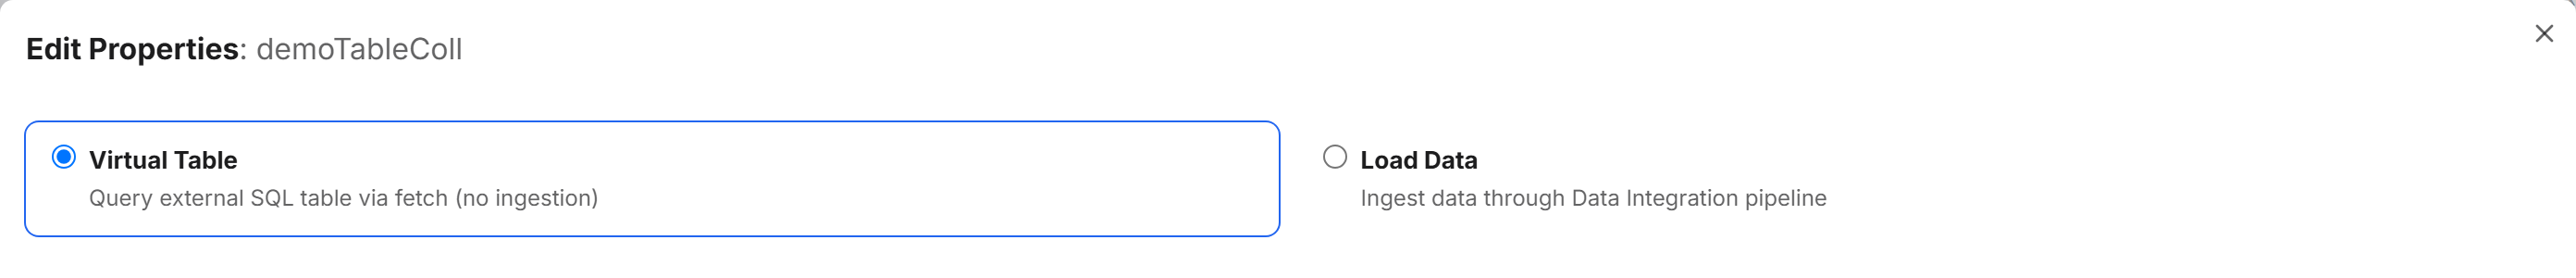
| Virtual Table | Load Data | |
|---|---|---|
| What it does | Queries the source table each time your application reads the Source Type | Copies new and changed rows into your target entity Type |
| Where the data lives | Only in the source database | In the source database and in your application's database |
| Transform | None runs | Maps the Source Type to your target entity Type |
| Settings in Edit Properties | None | Change Data Capture Configuration, Integration Schedule, and Stage records in files |
Virtual Table
In Virtual Table mode, the data stays in the source database. When your application calls fetch() or forId() on the Source Type, the platform sends a query to the source table and returns the current rows. No transform runs, so you read the columns as they are in the table.
The canvas shows a Transform placeholder under every External Entity Type node. You can configure the Transform in either mode, but the transform runs and copies the data into your application only in Load Data mode.
Use Virtual Table when:
- The table is large, but your application reads only a few rows at a time, selected by a filter.
- The source database holds the authoritative copy of the data and must serve all reads.
- Reads must always reflect the current data in the source.
- The table has no column whose values increase when a row changes, so CDC cannot find new and changed rows.
Each read in Virtual Table mode waits on the source database. If the database is slow or unavailable, your application's reads are slow or fail too.
Each read is also a new query on the source database. The platform writes the filter, sort order, and row limit of the fetch() call into the SQL query, so the source database does that work. A fetch() call returns at most 2,000 rows unless you set limit. To read more, raise limit or page with offset. Each page is a separate query.
Virtual Table also has these limits:
- The platform creates no table and no indexes for the Source Type. Reads use only the indexes in the source database.
- A filter cannot follow a reference between the Source Type and an entity Type stored in your application. For example, you cannot fetch your entity Type with a filter on a field of a Source Type it references.
Load the data instead when your application reads most of the table or reads the same rows many times. Also load the data when your application needs its own indexes on the data or filters across references to the data.
Load Data
In Load Data mode, a pipeline copies rows from the source table into your target entity Type with CDC. Each run reads the rows that changed since the last run, runs the transform, and stores the results. A transform is either a projection, which maps fields with expressions, or a transformer, which runs JavaScript code. You can also map into a canonical Type, an intermediate Type that several sources share, before you map to your target entity Type.
CDC uses the cdcOrder field of the source collection. The cdcOrder field names the column or columns that mark new and changed rows. In Data Fusion, you set cdcOrder under Order By Fields in Change Data Capture Configuration. The direction defaults to Ascending. Choose a column whose values increase whenever a row is added or changed, such as a last-modified timestamp or a sequence number.
The platform keeps one checkpoint for each source collection. The checkpoint holds the cdcOrder values of the last row read. Each run reads only rows with greater values, or lesser values for a descending order. To read the checkpoint of a collection, call its cdcCheckpoint() method.
By default, a Load Data collection sends rows straight from the source table to the transform. The Stage records in files toggle, off by default, writes the rows to files in a staging file source collection first and processes those files afterward. On a collection that does not stage, a process() call reads the changed rows, splits them into chunks, and updates the checkpoint before it returns. The chunks transform in the background, unless you pass doNotChunk: true. A collection that stages records processes its staged files in the background.
Use Load Data when:
- You want the application to hold its own copy of the data for fast reads.
- The source table has a column whose values increase whenever a row changes.
- Your application can accept some delay between a change in the source and its arrival in the application.
- You need to transform the rows, or combine them with other sources in a canonical Type, before your application reads them.
- Your application must keep reading the data when the source database is unavailable.
To set up CDC on the canvas, see Enable Change Data Capture for a SQL Source via UI. To set up CDC in code and to inspect or reset a sync, see Load Data Incrementally.
SQL connectors in Data Fusion
In Data Fusion, select Add Data Source to open the Configure Connector sheet. SQL connectors appear in several categories, including Database & data warehouse and Relational Databases. Every SQL connector creates a SQL source system. Many SQL connectors add an Advanced step to the wizard for optional settings. The connectors include:
| Connector tile | Database | Notes |
|---|---|---|
| Postgres | PostgreSQL servers | Optional SSL encryption on the Advanced step |
| SQL Server | Microsoft SQL Server instances, including Azure SQL | Username and password; for Azure SQL, turn on Encrypt connection on the Advanced step |
| Big Query | Google BigQuery datasets | OAuth, OAuth JWT for a service account, GCP instance account, or AWS or Azure workload identity |
| Delta Lake | Databricks workspaces | Personal access token, OAuth, or Azure sign-in methods |
| HANA | SAP HANA databases | Username and password |
| Snowflake | Snowflake warehouses | Key Pair or Programmatic Access Token; the account URL, database, and warehouse go on the Destination step |
| ServiceNow | ServiceNow tables, through a JDBC driver | Basic, OAuth, and single sign-on methods |
| Oracle, Redshift | Oracle databases and Amazon Redshift | Oracle has no Advanced step; Redshift adds one |
The sheet lists more SQL connectors, such as Teradata, Greenplum, MariaDB, CockroachDB, and Sybase, plus connectors for business applications that use third-party (CData) JDBC drivers. To find a connector, type its name in the search box of the Configure Connector sheet.
For the credentials each connector needs, see Authenticate Database Sources.
Infer the Source Type from a table
The platform can generate the Source Type from the table's columns. In Data Fusion, select Infer in the Define External Entity dialog to read the column names and types from the table. In code, call inferSourceTypes on the source system instance and pass an array of source collections; it returns one Type definition for each collection. To infer the Type for a single collection, call inferSourceType2 on that collection.
Build your first SQL pipeline
Before you start, make sure the application can reach the database over the network and that you have credentials for it. For the roles you need, see Data Integration Roles and Permissions.
The quickstart Connect with SQL Source System builds a SQL pipeline in Data Fusion with a Snowflake warehouse as the example. The quickstart takes these steps:
- Add the Snowflake connector with Add Data Source, authenticate with Key Pair or Programmatic Access Token, and select Save & Test on the Review step.
- Select a table, which creates a SQL Source Collection node, then describe its columns in the Define External Entity dialog, which adds the External Entity Type node.
- In the Edit Properties dialog of the collection, select Load Data and set the Order By Fields.
- Map the fields in the Transform to a target entity Type, then run the pipeline with Execute pipeline.
To build a Load Data pipeline in code from the C3 AI Console, see Ingest a Snowflake Table Programmatically. For Virtual Table in code, see Query a Snowflake Table Programmatically with Virtualization.