Connect Application to Google BigQuery
The C3 Agentic AI Platform has a built-in Java Database Connectivity (JDBC) connector for integrating with Google BigQuery.
C3 AI Studio offers Data Fusion, a visual tool for building data pipelines. Data Fusion configures data sources and connects them to C3 Canonicals and Entities. For more information, see Data Fusion Overview.
To connect to BigQuery from your application:
- Add a SqlSourceSystem modeling the BigQuery source system to your package.
- Configure the JdbcCredentials authorizing the connection to the external BigQuery table.
- Add a SqlSourceCollection modeling the target BigQuery table to your package.
- Create an External Type modeling the schema of the external BigQuery table.
For more information, see the documentation for CData JDBC Driver for Google BigQuery.
Model the source system
Create a SqlSourceSystem and set the name field as the identifier for the external database system.
For example, add the following BigQuerySourceSystem.json to the \metadata\SqlSourceSystem directory of your package:
{
    "name": "BigQuerySourceSystem"
}Configure the credential used to authorize the JDBC connection
You can configure the JDBC connector to provide credentials and authenticate the connection to your database with one of the following methods:
- Using a Google User Account
- Using a Google Service Account
- Using pre-generated access and refresh tokens
- Using application default credentials
- Using an external account
If the C3 Agentic AI Platform runs on the Google Cloud Platform (GCP), use a Google Service Account (GSA) configured with Workload Identity. C3 AI does this configuration by default. After you obtain your GSA, assign the account the correct permissions in your BigQuery cluster. At minimum, the GSA needs the BigQuery Job User and BigQuery Data Viewer roles.
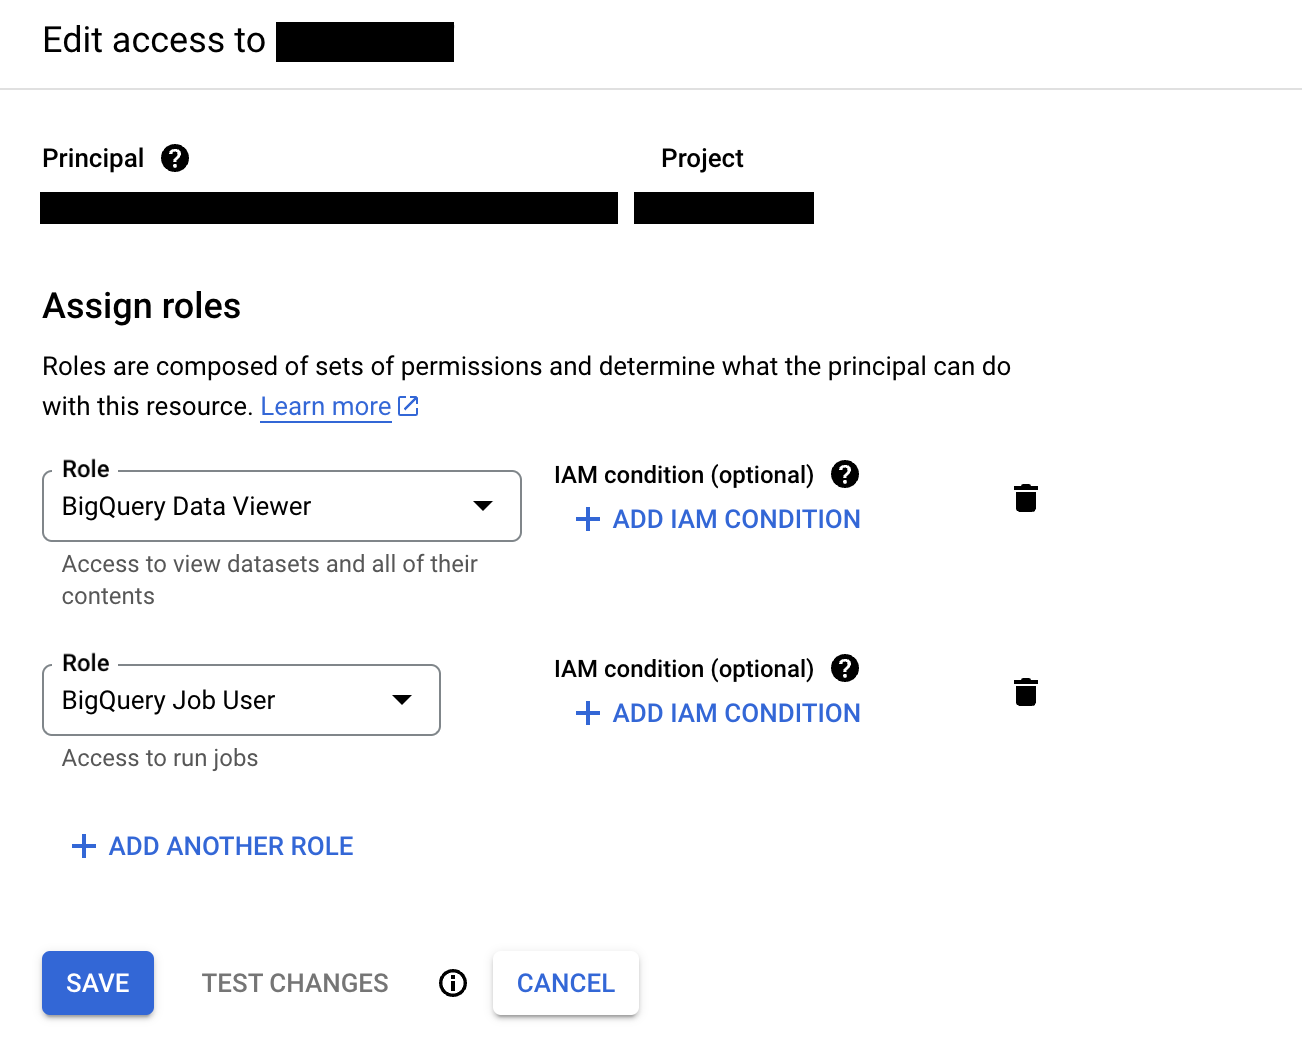
You can grant permissions at the organization, project, or dataset level.
Next, create a JdbcCredentials Type instance to configure the connection to the external BigQuery cluster.
var credsRaw = {
"name": "< USER DEFINED NAME >",
"datastore": DatastoreType.GOOGLEBIGQUERY,
"url": "jdbc:googlebigquery:AuthScheme=GCPInstanceAccount;ProjectId=< MY_PROJECT_ID >;DatasetId=< MY_DATASET_ID >"
}

creds = JdbcCredentials.make(credsRaw)
SqlSourceSystem.forName("BigQuerySourceSystem").setCredentials(creds);- If you grant permissions at the project level, the
DatasetIdfield is optional. - If you grant permissions at the organization level, both
DatasetIdandProjectIdare optional.
If you bill queries to a different project from the one that contains the data, specify the billing project as the ProjectId.
Connect BigQuery with a service account
A service account authenticates and authorizes access to BigQuery with its own credentials. C3 AI applications can then work with BigQuery without individual user credentials.
Before you start, verify that your project includes the dependencies or libraries that provide the SqlSourceSystem class.
Set up connection to Google BigQuery using a service account
Establish a secure connection to Google BigQuery with a service account for the SQL source system BigQuerySourceSystem.
Create a service account:
- Go to the Google Cloud Console.
- Go to IAM & Admin > Service Accounts.
- Select Create Service Account.
- Fill in the details and select Create.
- Assign the required roles, for example BigQuery Data Viewer.
- Download the JSON key file.
Prepare the service account JSON:
- Open the downloaded JSON key file.
- Copy the contents of the file.
Set up variables in your code:
Define the name of the SQL source:
JavaScriptvar sysName = 'BigQuerySourceSystem';Store the service account JSON credentials:
JavaScriptvar content = `{ "type": "service_account", "project_id": "your_project_id", "private_key_id": "your_private_key_id", "private_key": "your_private_key", "client_email": "your_client_email", "client_id": "your_client_id", "auth_uri": "your_auth_uri", "token_uri": "your_token_uri", "auth_provider_x509_cert_url": "your_auth_provider_x509_cert_url", "client_x509_cert_url": "your_client_x509_cert_url" }`;Set the JDBC URL:
JavaScriptvar url = "jdbc:googlebigquery:<your connection string>";
Configure JDBC credentials for Google BigQuery using OAuthJWT
Configure JDBC credentials that connect securely to Google BigQuery with OAuth 2.0 and a JSON Web Token (JWT).
Define authentication properties:
Create a properties dictionary that sets the authentication scheme and includes the service account JSON credentials.
JavaScriptvar properties = { "AuthScheme": "OAuthJWT", "OAuthJWTCertType": "GOOGLEJSONBLOB", "OAuthJWTCert": content }Build JDBC credentials:
Use the
JdbcCredentials.builder()method to build the credentials object with the URL, properties, and datastore type.JavaScriptcreds = JdbcCredentials.builder().url(url) .username("******") .password("******") .properties(properties) .datastore("googlebigquery").build();Set credentials using
SqlSourceSystem:Get the
SqlSourceSystemfor the system name and set the credentials.JavaScriptSqlSourceSystem.forName(sysName).setCredentials(creds);Test the connection:
Run a test query against Google BigQuery to confirm that the setup works.
Connect to Google BigQuery using SqlSourceSystem
Use the SqlSourceSystem to connect to Google BigQuery and list the available table names.
Retrieve the
SqlSourceSystem:Use the
forNamemethod to get theSqlSourceSysteminstance for the system name.JavaScriptsys = SqlSourceSystem.forName(sysName)Establish the connection:
Call the
connectmethod on theSqlSourceSysteminstance to connect to Google BigQuery.JavaScriptsys.connect()List table names:
Use the
listTableNamesmethod to return the names of the tables in the connected BigQuery dataset.JavaScriptsys.connect().listTableNames()Verify the connection:
Confirm that the connection succeeds and the table names are listed. A correct list confirms the setup and the connection.
Model the table containing the data
To model the external BigQuery table in your application, create a SqlSourceCollection and set the following fields:
name: Identifier for the BigQuery tablesource: Name of theExternalType that models the schema of the external BigQuery tablesourceSystem: Name of the BigQuerySqlSourceSystem
For example, to model a table called iris, add the following BigQueryTable.json to the \metadata\SqlSourceCollection directory of your package:
{
    "name" : "IrisBigQuery",
    "source" : "IrisBigQuery",
    "sourceSystem" : {
      "type" : "SqlSourceSystem",
      "name" : "BigQuerySourceSystem"
    }
}Model the table schema
To model the schema of the BigQuery table in your application, create an External entity Type. Give the entity Type a schema name that matches the fully qualified name of the table exactly. The schema name is case sensitive.
Start by adding the following IrisBigQuery.c3typ file to the \src directory of your package:
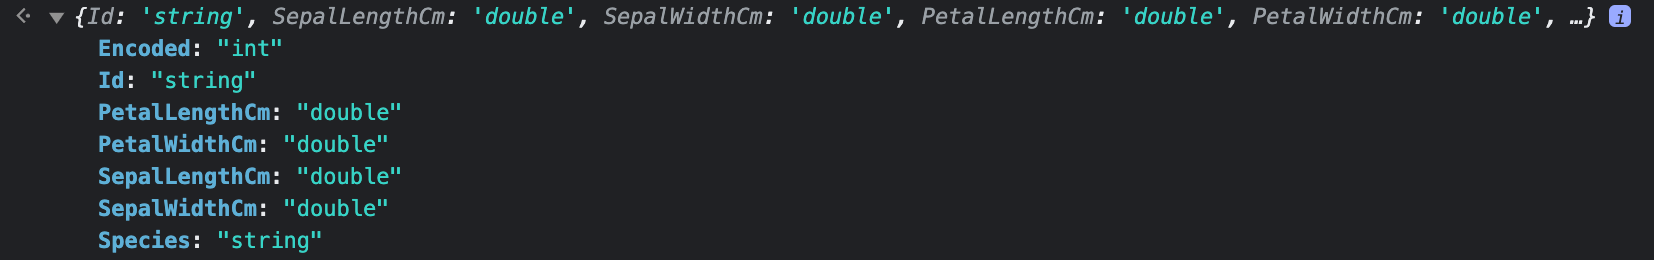
entity type IrisBigQuery mixes External, NoSystemCols schema name 'dev.iris'For the iris table, the schema name is a qualified name: the dataset and the table name, separated by a dot. The project name comes from the credentials you set earlier. Use the inferSourceType() method to see the C3 AI data types that the C3 Agentic AI Platform infers from the source data types of the table:
The inferSourceType() method does not work if the table is a materialized view.
var schema = SqlSourceCollection.forName("IrisBigQuery").inferSourceType().declaredFieldTypes;

var myObject = {};
for (let i = 0; i < schema.length; i++) {
        schemaName = schema[i].schemaName;
        myObject[schemaName] = schema[i].valueType.name;
    }
The platform maps BigQuery data types to PrimitiveType according to the following table:
| BigQuery Data Types | C3 AI Data Types |
|---|---|
| INT64 | int, int16, int32, bigint |
| NUMERIC, BIGNUMERIC | decimal |
| FLOAT64 | float, double |
| BOOL | boolean |
| STRING | string |
| BYTES | byte |
| DATE, DATETIME, TIME, TIMESTAMP | datetime |
| STRUCT, JSON | json |
| GEOGRAPHY | Not Supported |
To validate the type inference, view the source data types:
SqlSourceCollection.forName("IrisBigQuery").connect().columns;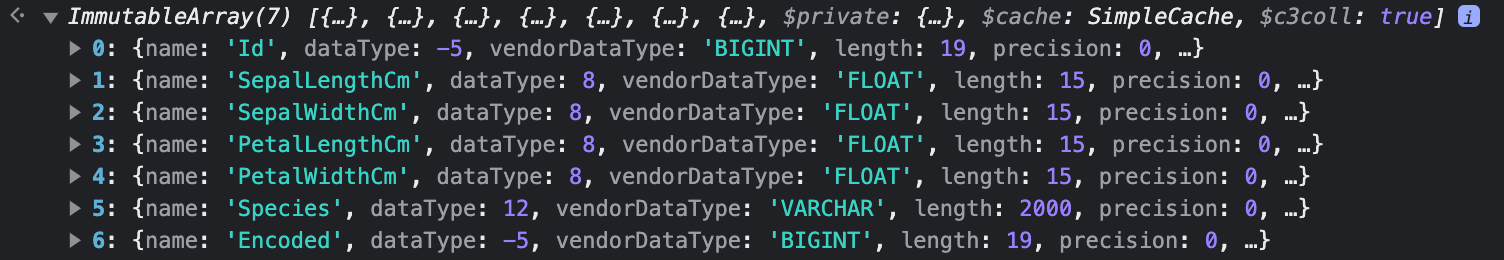
Complete the External entity Type definition:
entity type IrisBigQuery mixes External, NoSystemCols schema name 'dev.iris' {

  id: ~ schema name "Id"

  sepalLengthCm: double schema name "SepalLengthCm"

  sepalWidthCm: double schema name "SepalWidthCm"

  petalLengthCm: double schema name "PetalLengthCm"

  petalWidthCm: double schema name "PetalWidthCm"

  species: string schema name "Species"

  encoded: int schema name "Encoded"
}
You must include the id field. If your table has no column called id, change the schema name for the corresponding id field with the following annotation:
@db(dataTypeOverride="< ID_FIELD_DATA_TYPE >")
id: ~ schema name "< ID_FIELD >"Read data from the table
After you set the credential, validate the configuration. Fetch the External Type data from the BigQuery table:
c3Grid(IrisBigQuery.fetch());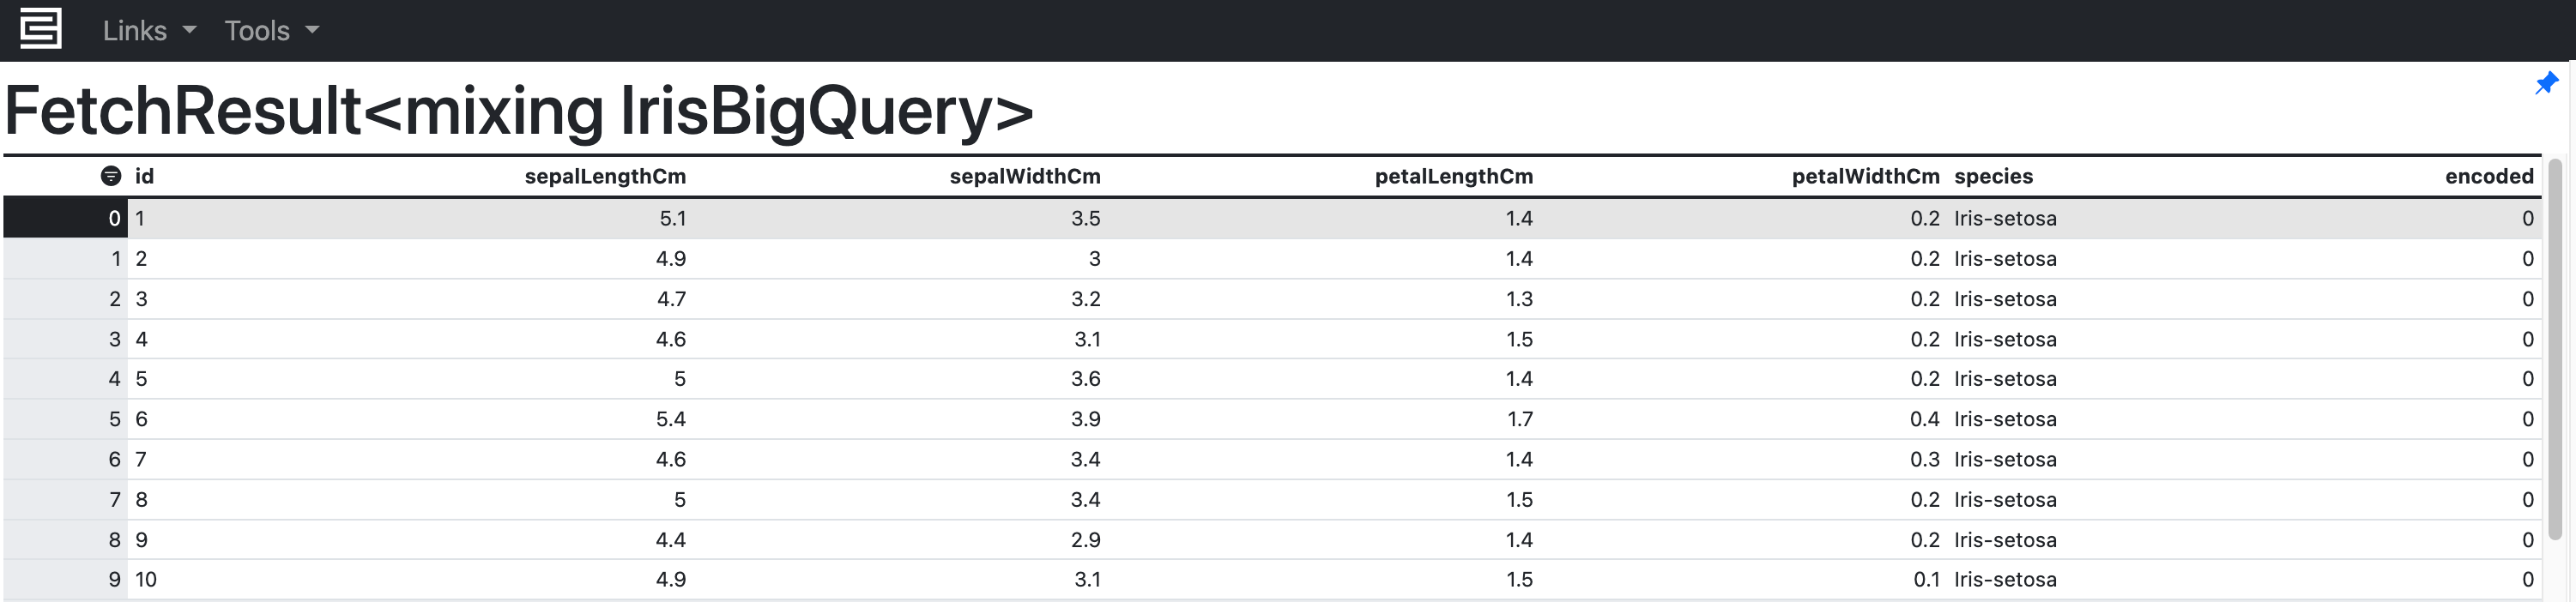
Write data to BigQuery tables
You can also write data from the C3 Agentic AI Platform back to BigQuery tables.
To write data to an existing BigQuery table from your application, do the following:
- Create a primary key constraint in the BigQuery table.
- Update the JDBC connection URL with the insert mode and primary keys.
- Insert new records with the
createorcreateBatchAPIs, or update existing records with themergeormergeBatchAPIs.
The following sections use an example table called Asset.
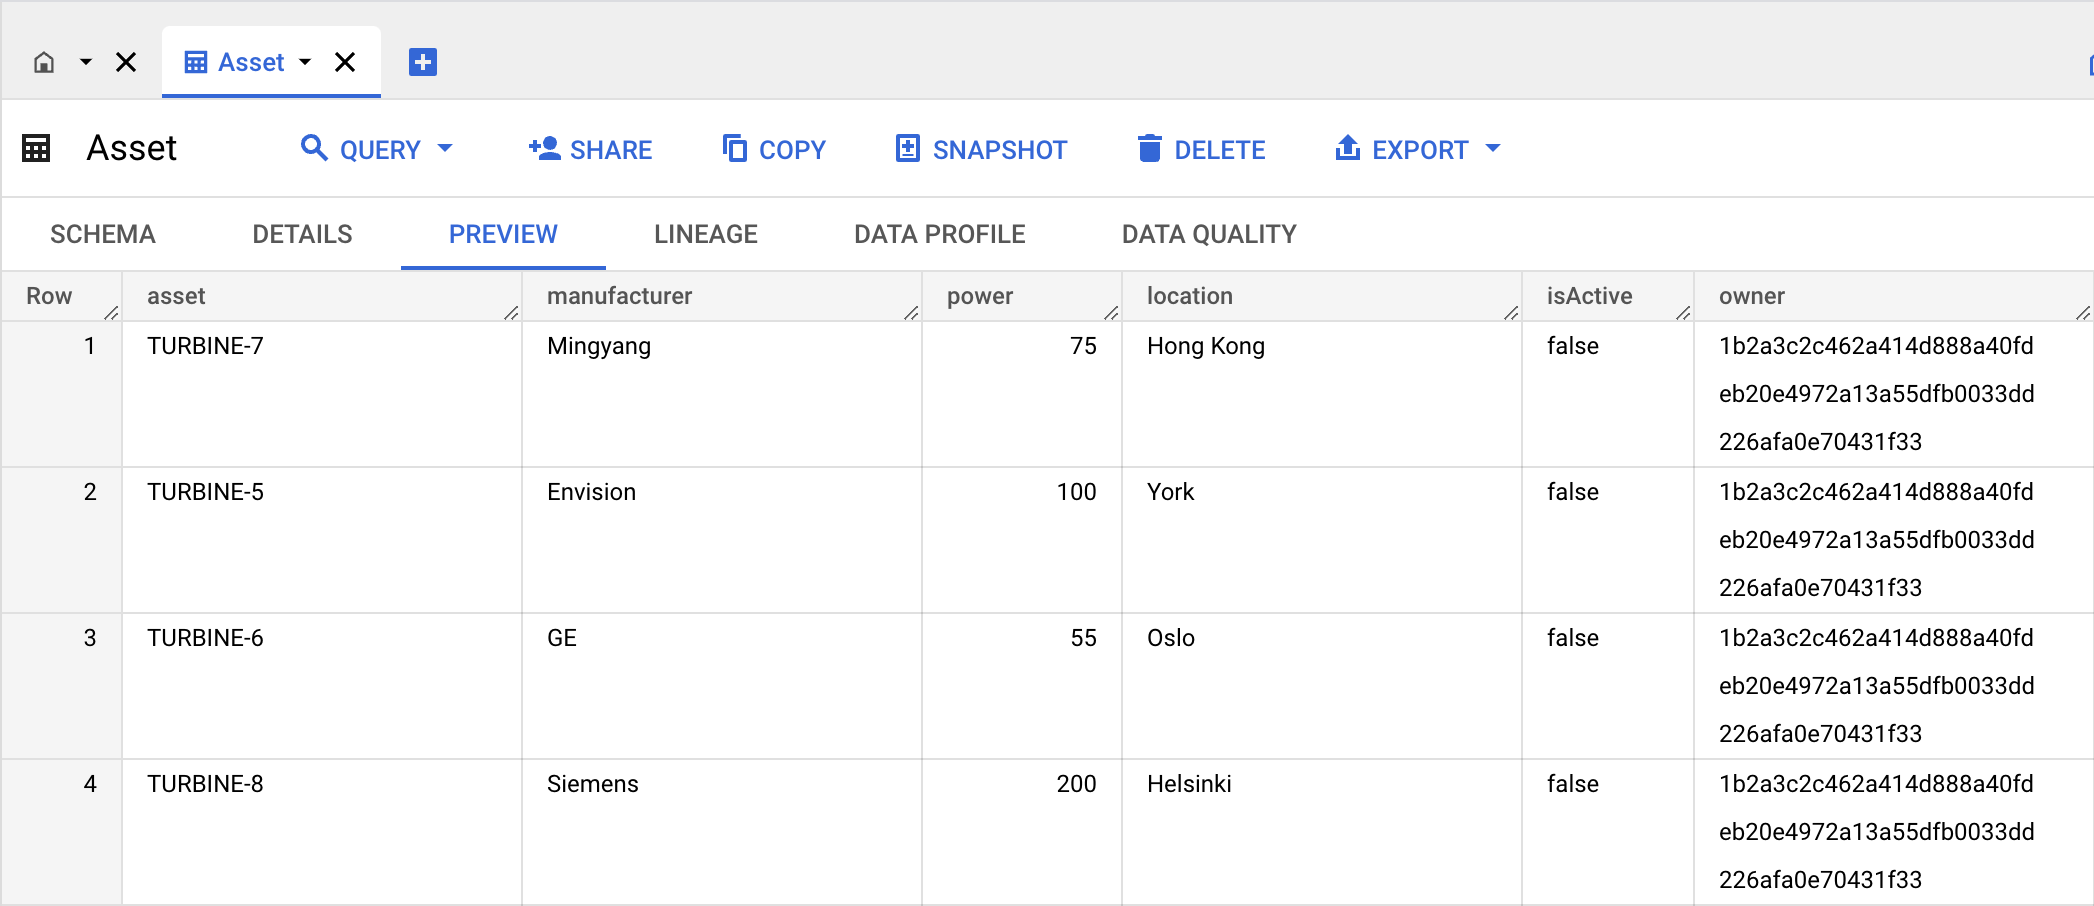
Create a primary key constraint
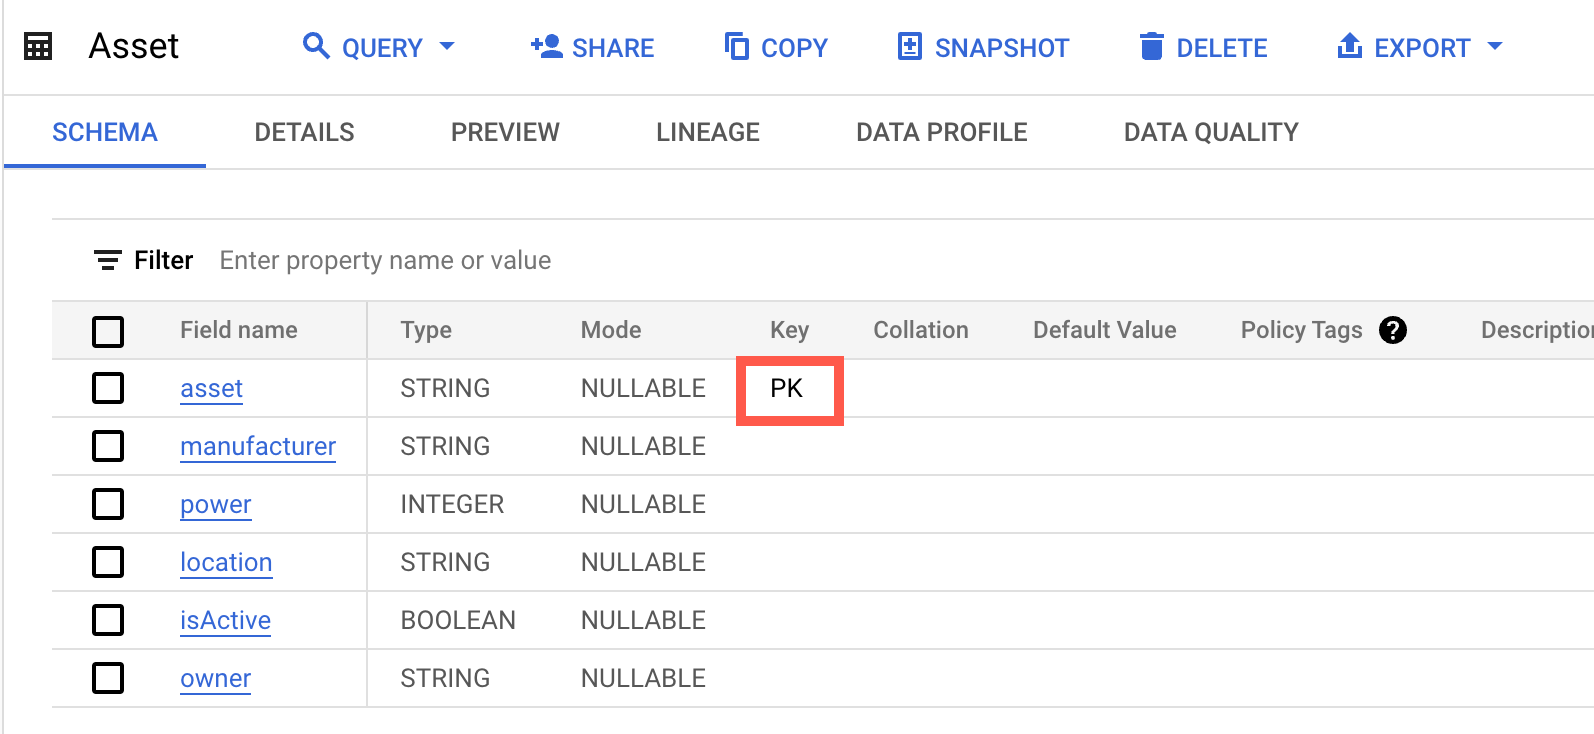
To set the asset field as the primary key, run the following SQL statement:
ALTER TABLE `aml-demo-317700.aml.Asset` ADD PRIMARY KEY (asset) NOT ENFORCED;Verify that the asset field is the primary key by inspecting the table schema.
Update the JDBC connection URL
The C3 Agentic AI Platform writes data to BigQuery through a temporary Google Cloud Storage (GCS) staging bucket, instead of the default streaming mode. Append the following snippet to the JDBC connection URL:
InsertMode=GCSStaging;GCSBucket=< MY_BUCKET >;PrimaryKeyIdentifiers=< KEYS >InsertMode: The method for writing to BigQuery.GCSBucket: The name of the GCS bucket, in the same location as the BigQuery table.PrimaryKeyIdentifiers: A list of rules that define the primary keys. For more information, see PrimaryKeyIdentifiers in the JDBC driver for Google BigQuery.
Create another JdbcCredentials Type instance to reconfigure the connection.
var credsRaw = {
"name": "< USER DEFINED NAME >",
"datastore": DatastoreType.GOOGLEBIGQUERY,
"url": "jdbc:googlebigquery:AuthScheme=GCPInstanceAccount;ProjectId=< MY_PROJECT_ID >;DatasetId=< MY_DATASET_ID >;InsertMode=GCSStaging;GCSBucket=< MY_BUCKET >;PrimaryKeyIdentifiers=< KEYS >"
}

creds = JdbcCredentials.make(credsRaw)
SqlSourceSystem.forName("BigQuerySourceSystem").setCredentials(creds);
In this example, the primary key property is PrimaryKeyIdentifiers='*=id;Asset=asset'.
Create or modify table records
After you add a SqlSourceCollection and an External Type for the Asset table, you can create or modify records.
In this example, the C3 Agentic AI Platform holds the following three records.
objs = [{
  "id": "TURBINE-1",
  "manufacturer": "Goldwind",
  "power": "50",
  "location": "Streator",
  "isActive": "false",
  "owner": "create"
}, {
  "id": "TURBINE-2",
  "manufacturer": "Nordex",
  "power": "125",
  "location": "Cambridge",
  "isActive": "true",
  "owner": "create"
}, {
  "id": "TURBINE-3",
  "manufacturer": "GE",
  "power": "125",
  "location": "Clinton",
  "isActive": "false",
  "owner": "create"
}]
To insert the three records into the BigQuery table, use the createBatch API:
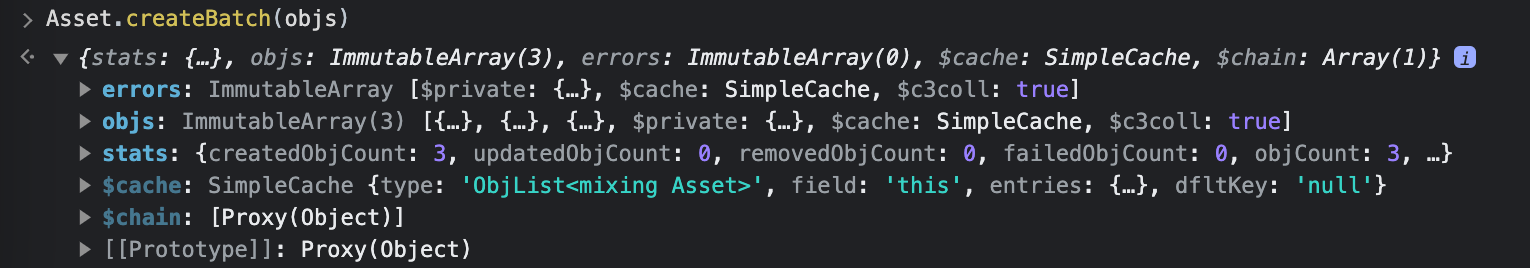
The new records are now in the table:
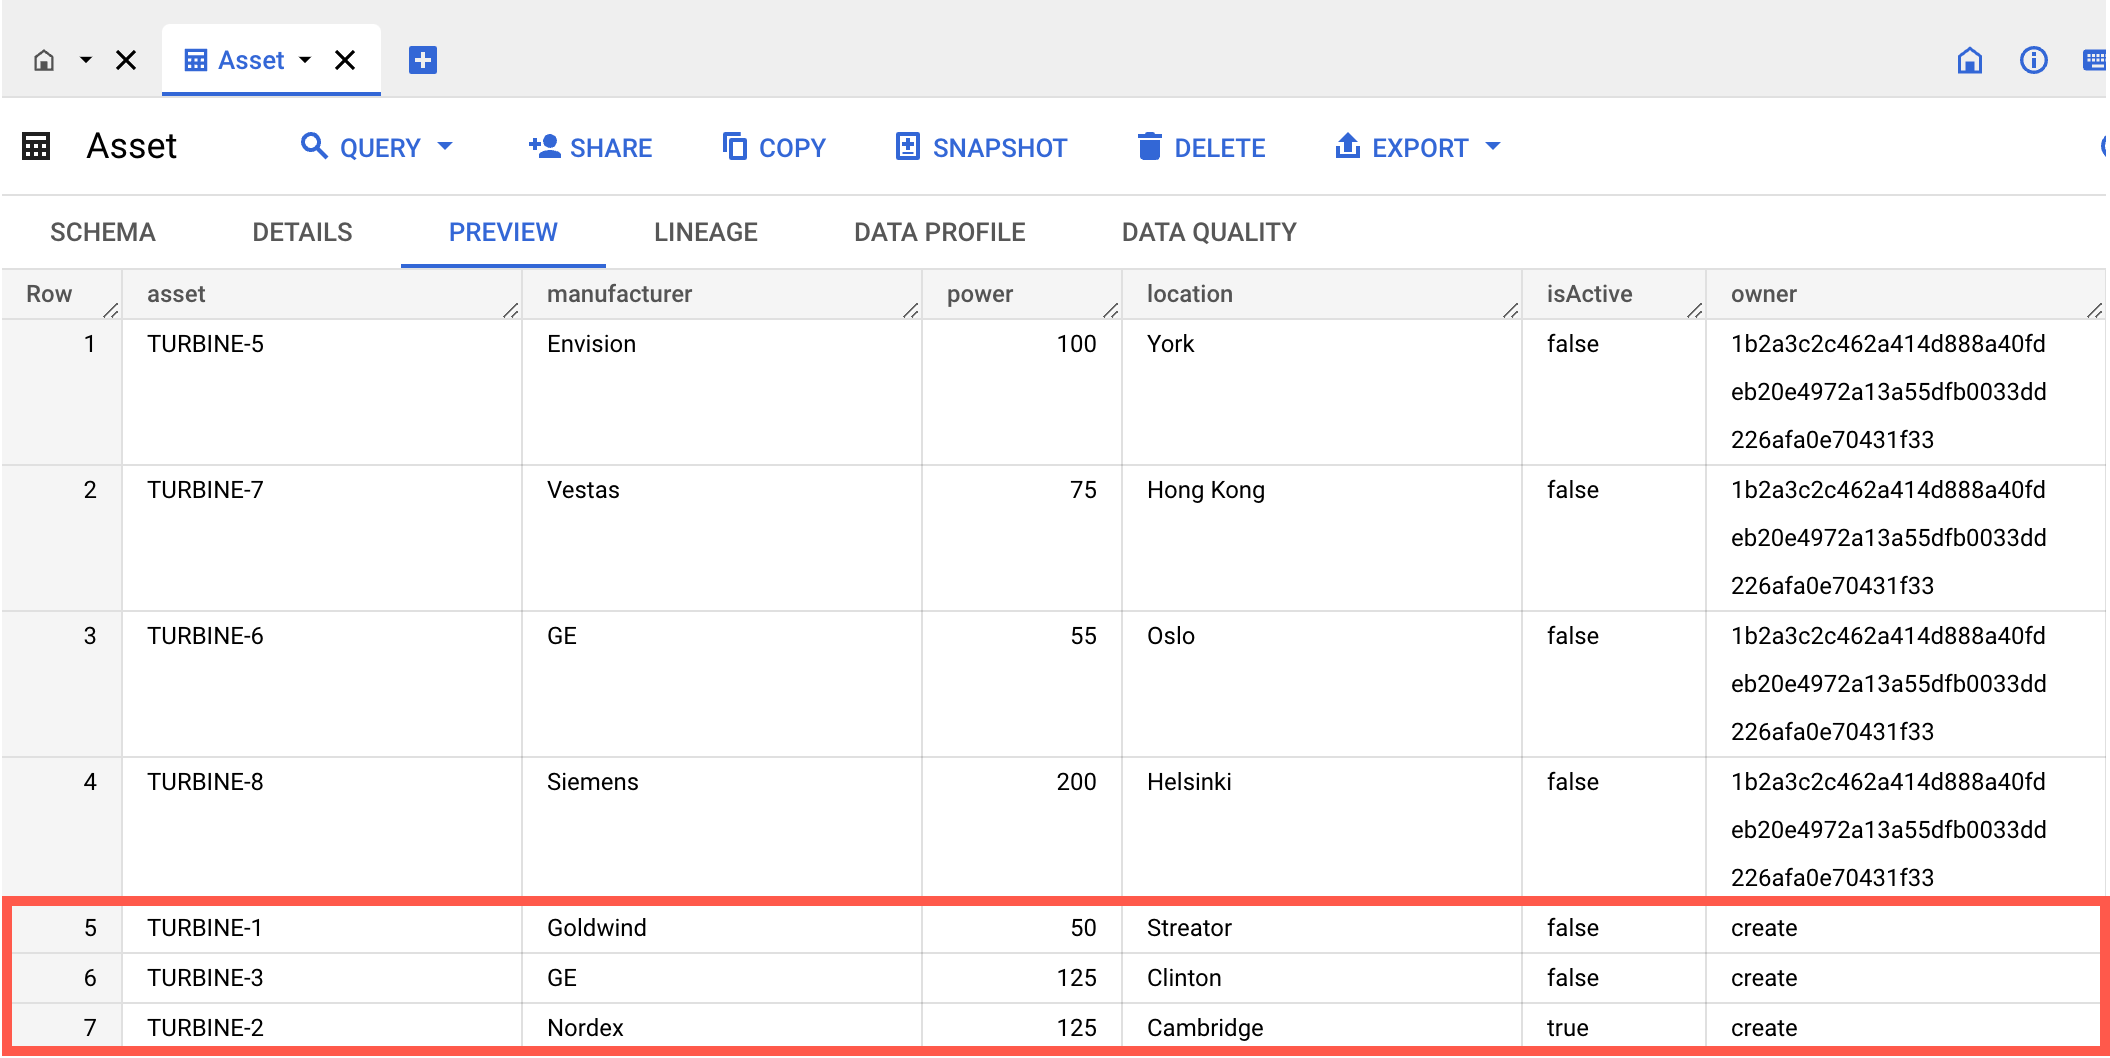
Next, the assets with IDs TURBINE-1 and TURBINE-3 become active, and their isActive properties change from false to true.
objs = [{
  "id": "TURBINE-1",
  "manufacturer": "Goldwind",
  "power": "50",
  "location": "Streator",
  "isActive": "true",
  "owner": "create"
}, {
  "id": "TURBINE-3",
  "manufacturer": "GE",
  "power": "125",
  "location": "Clinton",
  "isActive": "true",
  "owner": "create"
}]
To update the existing records in the BigQuery table, use the mergeBatch API:
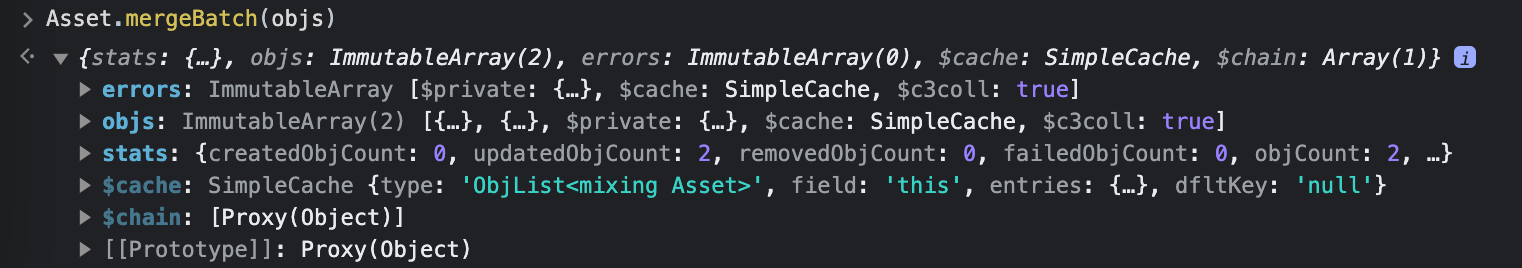
The updates are now visible in the table:
